在工業相機的實作中,我曾遇到 YOLOv7 無法即時更新畫面的情況,因此改用 YOLOv5 繼續測試。這篇把環境建置、資料標註、模型訓練與即時偵測串成一條流程,也留下除錯與延伸開發的紀錄。

本篇重點
  • 先建立獨立環境,再準備圖片、標籤與資料設定
  • 用訓練結果中的 best.pt 執行偵測
  • 依症狀查閱錯誤處理與相機、裁圖、通訊範例

原始實作記錄於 2022 年;以下操作畫面與程式範例保留當時版本。

以下是我在工業相機專案中使用 YOLOv5 的學習與除錯紀錄。

YOLOv7 在我當時的工業相機環境中,影像來源初始化時顯示:1/1: 0... success (640x480 at 0.00 FPS).。這個畫面不足以單獨判斷模型有問題,還需要檢查相機與影像讀取流程。
YOLOv5 與 YOLOv7 的部分操作指令類似。當時在自己的相機與程式環境中,YOLOv7 沒有順利更新影像,因此我改用 YOLOv5 繼續實作。這是特定環境的經驗,不能推論所有專案都有同樣限制。

YOLOv5 實作紀錄:從資料標註到工業相機偵測:原文圖片 01

YOLOv5-ultralytics-Github:https://github.com/ultralytics/yolov5 (Chinese 中文簡體說明)
閱讀以下範例時,請先對照當時的版本、目錄與相機來源,再調整成自己的設定。

操作說明

  • 使用 Anaconda 管理 Python 環境,讓相依套件與其他專案分開。
  • 至Anaconda官網選擇符合系統與專案需求的版本:https://www.anaconda.com/products/distribution
  • 安裝完成後,使用 Anaconda Prompt (anaconda3) 來建立 YOLOv5 開發環境。

建立 YOLOv5 開發環境

  1. 建立 Python 新環境

    1
    conda create -n yolov5-py3.9 python=3.9.13
    1
    conda activate yolov5-py3.9
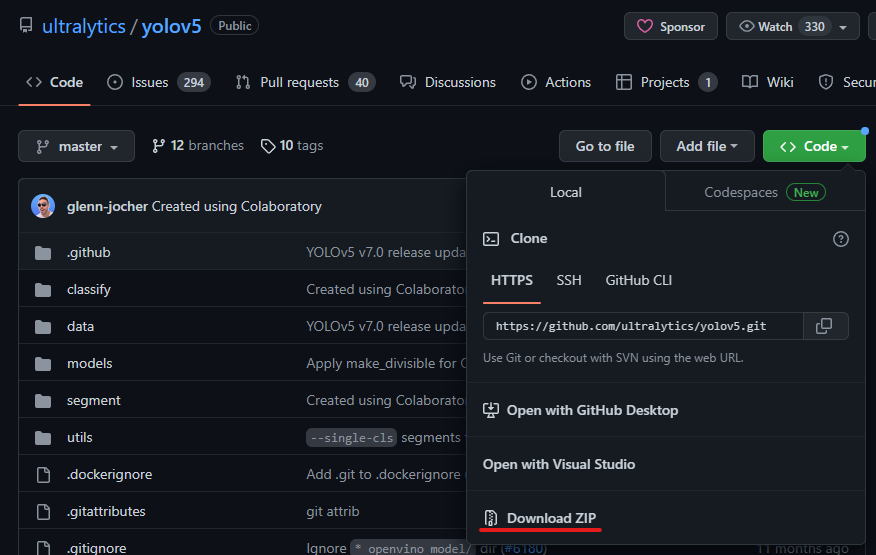
  2. 至 YOLOv5 的 Github 下載:https://github.com/ultralytics/yolov5
    建立YOLOv5環境:原文圖片 02

  3. 解壓縮下載的yolov5-master.zip的檔案

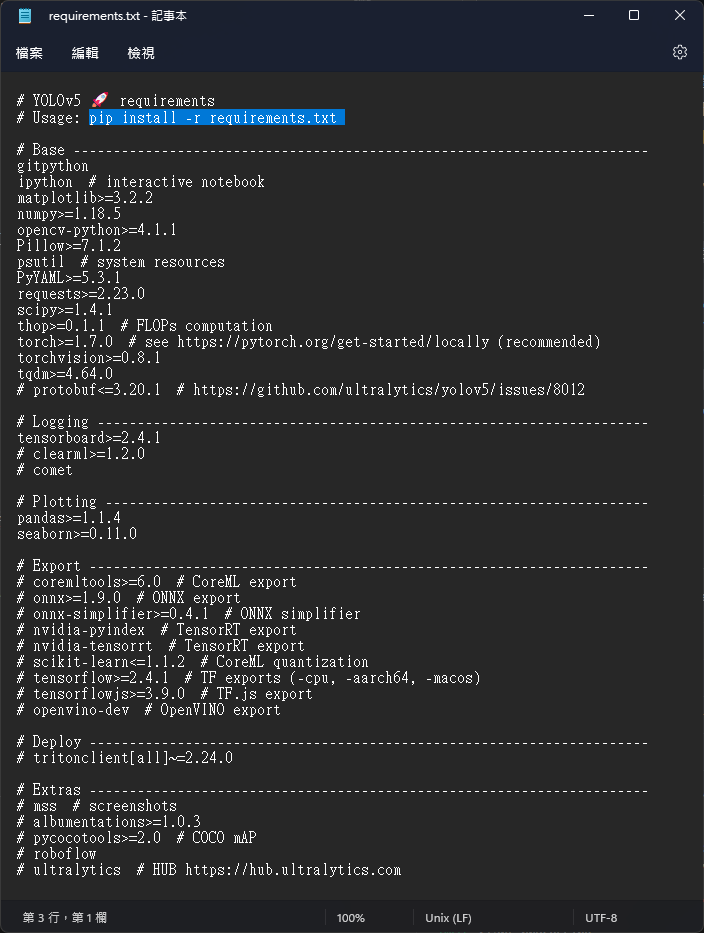
  4. 由於YOLO各版本都會有提供安裝模組清單,cd 至 yolov5-master 的資料夾,就可以安裝 YOLOv5 所需套件

    (點擊展開)如果有報錯 `warning: ignore distutils configs in setup.cfg due to encoding errors.` 解決辦法: 建立YOLOv5環境:原文圖片 03
    1
    pip install -r requirements.txt
    建立YOLOv5環境:原文圖片 04
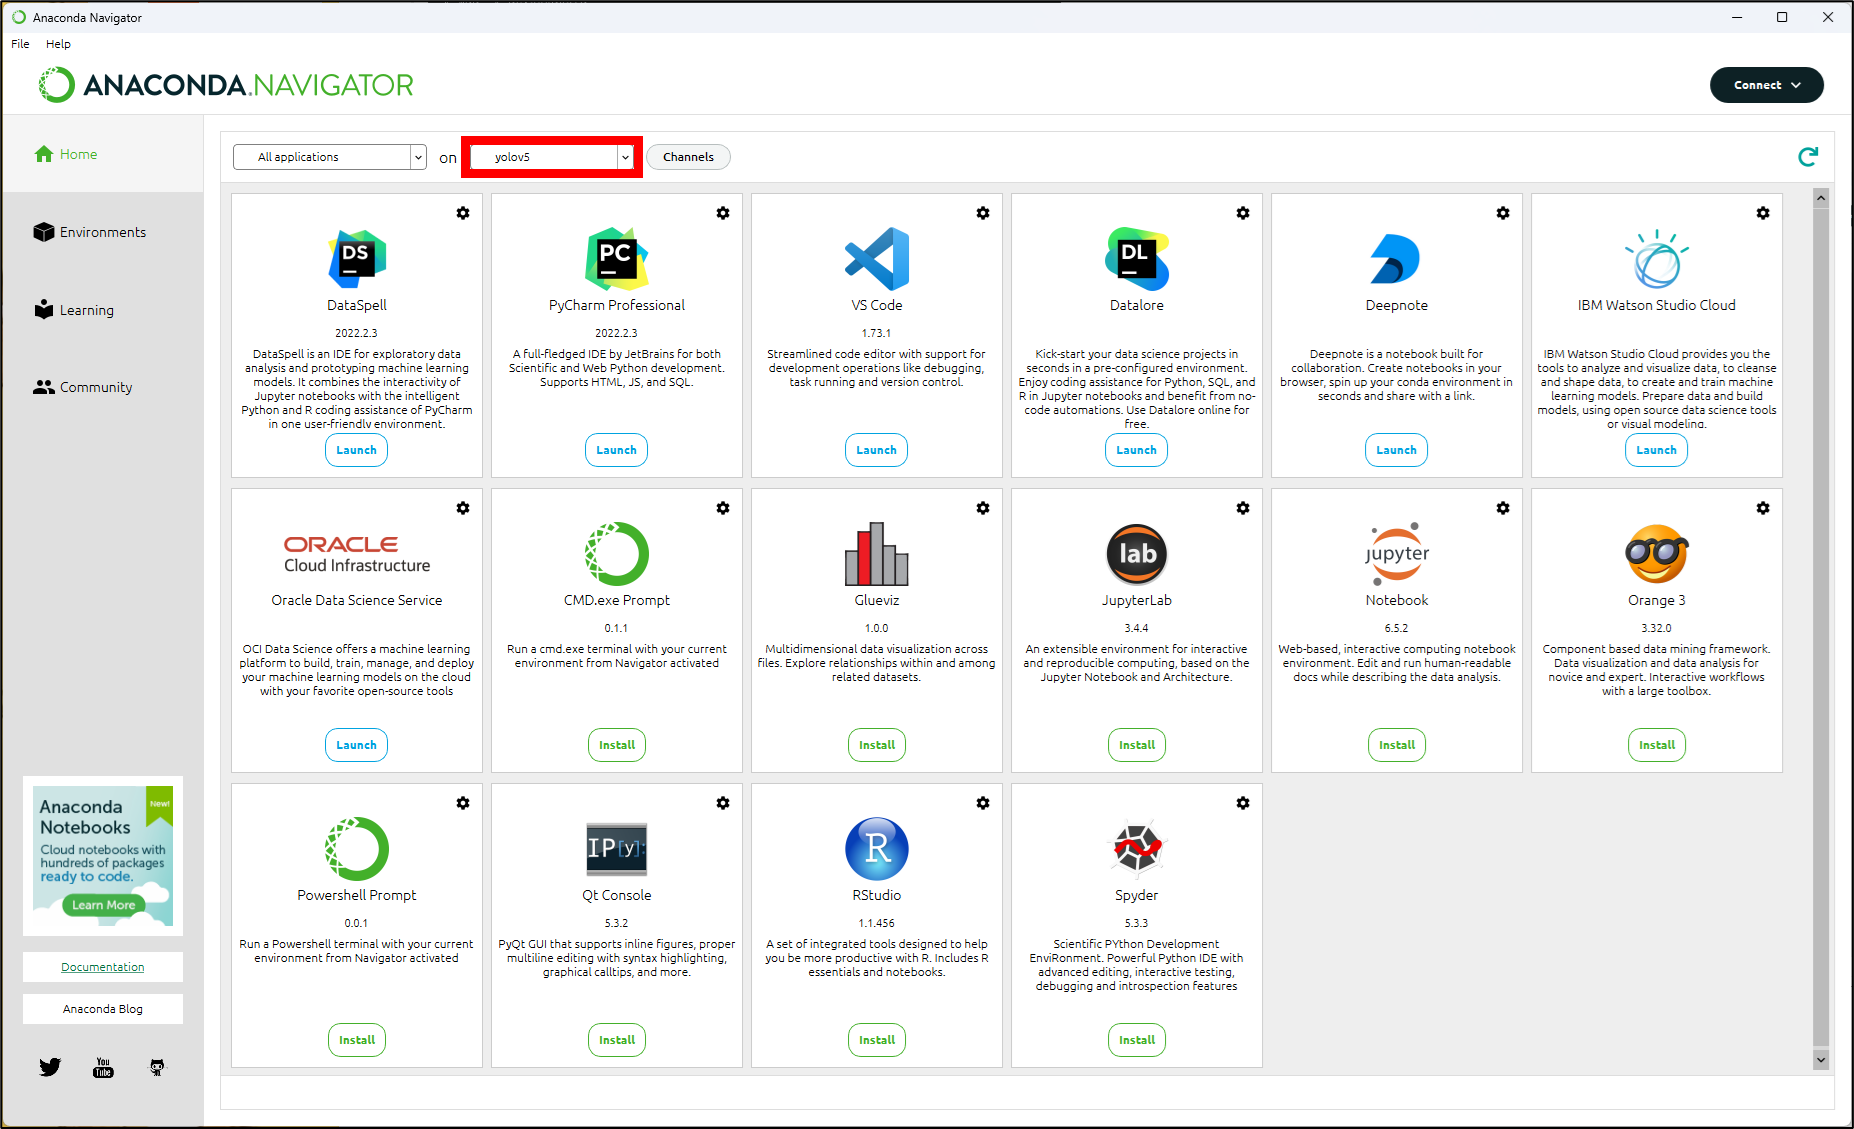
  5. 開啟Anaconda Navigator,切換環境到剛剛建立的yolov5
    Anaconda Navigator

  6. 在上個步驟的Anaconda Navigator介面下安裝:

  • Notebook、CMD.exe Prompt
    若有其他開發需求,再安裝相應工具。

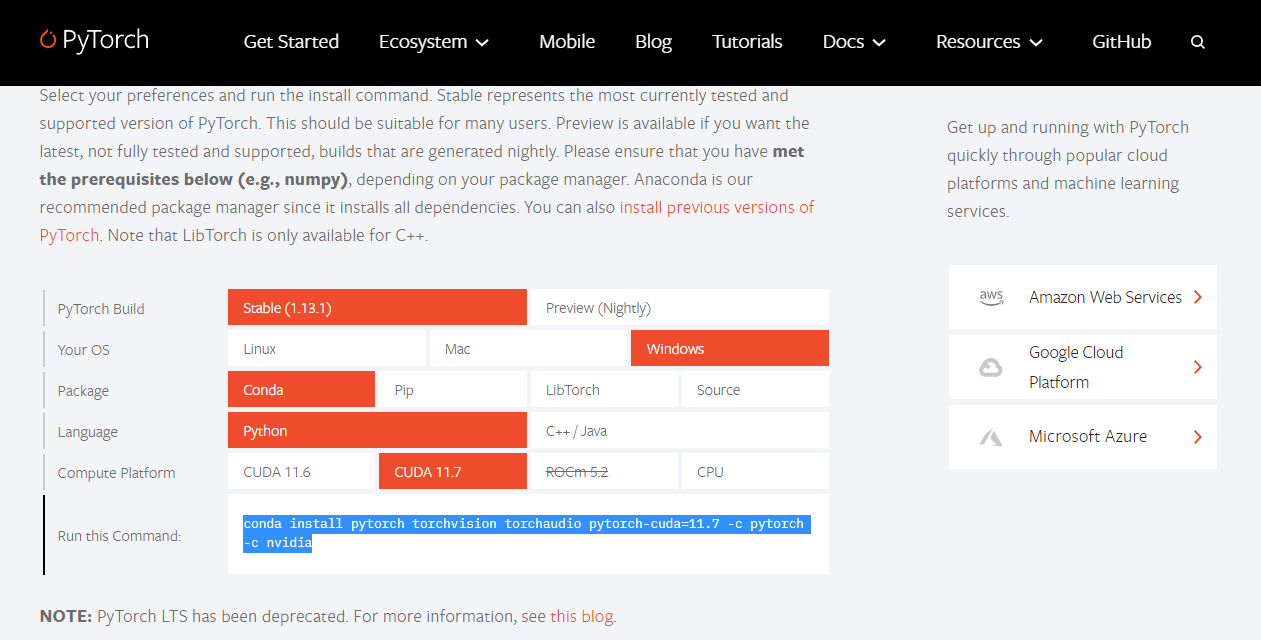
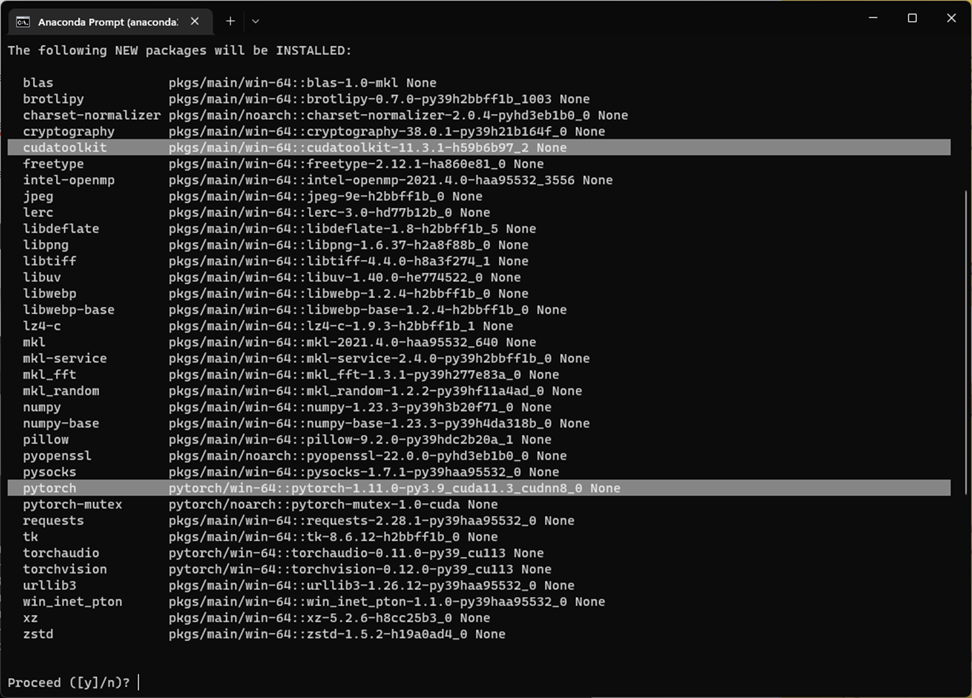
  1. 安裝Pytorch-cuda,官網:https://pytorch.org/
    Pytorch官網歷史版本:https://pytorch.org/get-started/previous-versions/
    本篇 2022 年實作選用當時的 Stable (1.13.1)的Pytorch版本。

建立YOLOv5環境:原文圖片 06

  • 安裝指令:
    1
    conda install pytorch torchvision torchaudio pytorch-cuda=11.7 -c pytorch -c nvidia
  • 示意圖:
    建立YOLOv5環境:原文圖片 07
  1. 完成 YOLOv5 環境安裝後,先確認能執行專案,再進入標註與訓練。安裝成功不代表相機或訓練流程已驗證完成。

  2. 以下另列出這份專案使用的套件。它們是當時的開發需求,請依自己的功能選擇,不必把所有套件都視為 YOLOv5 的必要條件。

    1
    pip install PyQt5
    1
    pip install pyqt5-tools
    1
    pip install eventlet
    1
    pip install chardet
  • 備註:

    QT5 Designer中文使用介面位置:

    1
    C:\Users\使用者\anaconda3\envs\環境名稱\Lib\site-packages\qt5_applications\Qt\bin\`designer.exe`

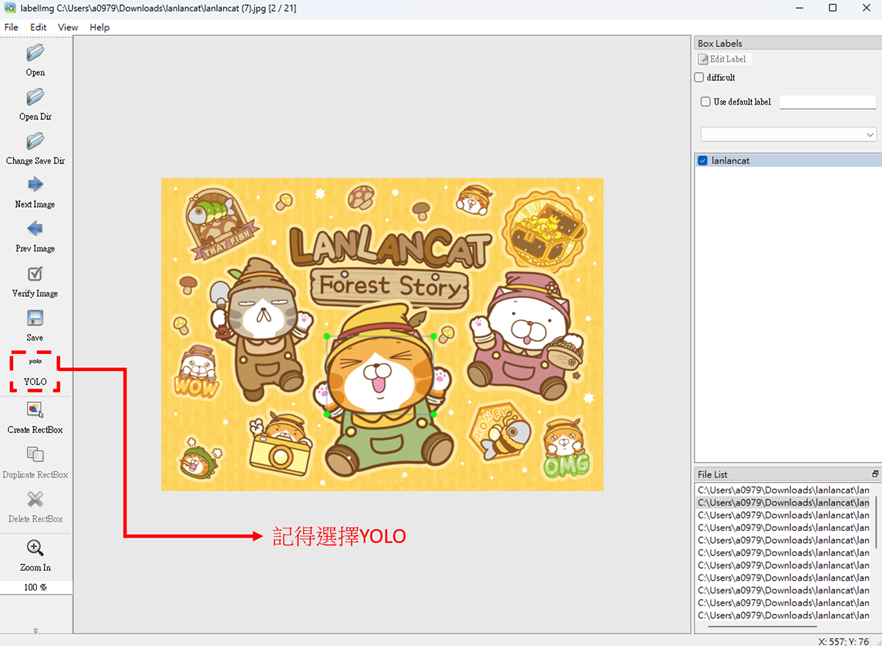
使用 labelImg 標註圖片

先決定類別名稱與編號,再以相同規則標註所有圖片。完成後抽查圖片與標籤是否一一對應,確認儲存格式符合這份 YOLO 專案的設定。

1
pip install labelimg
  • 執行時,在Anaconda Prompt (yolov5)上輸入labelimg,會跳出以下畫面:
    1
    labelimg

    示意圖


擷取影像與建立樣本

利用工業相機拍攝影片,將影片的各幀畫面擷取成照片,每張以名稱與流水號存入影像資料夾,再篩選需要的樣本。

1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
43
44
45
46
47
48
49
50
51
52
53
54
55
56
57
58
59
60
61
62
63
64
65
import cv2
import os
import shutil

a=input("請輸入資料夾名稱(請以英文命名):")
b=input("請輸入張數:")
enter=int(b)
# ----------
# 開啟攝像頭
cap = cv2.VideoCapture(0) # 選擇運行攝影機(預設為0)
# 視訊大小設定,獲取幀寬度,獲取幀高度
sz = (int(cap.get(cv2.CAP_PROP_FRAME_WIDTH)), int(cap.get(cv2.CAP_PROP_FRAME_HEIGHT)))
fps = 30
# 輸出格式
fourcc = cv2.VideoWriter_fourcc(*'mp4v')
# open and set props
vout = cv2.VideoWriter()
vout.open(a+'.mp4', fourcc, fps, sz, True)

cnt = 1
while cnt <= enter:
_, frame = cap.read()
# putText輸出到視訊上,各引數依次是:照片/新增的文字/左上角座標/字型/字型大小/顏色/字型粗細
cv2.putText(frame, str(cnt), (10, 20), cv2.FONT_HERSHEY_PLAIN, 1, (0, 255, 0), 1, cv2.LINE_AA)
vout.write(frame)
cnt += 1

cv2.imshow('vidio', frame)
cv2.waitKey(30)

vout.release()
cap.release()
# ----------------------------------------
video_path = a+'.mp4'
output_folder = './'+a+'/'

if os.path.isdir(output_folder):
print("刪除資料夾: {}".format(output_folder))
shutil.rmtree(output_folder)

os.mkdir(output_folder)
print("新建資料夾: {}".format(output_folder))
# ----------------------------------------
# 建立圖片
vc = cv2.VideoCapture(video_path)
fps = vc.get(cv2.CAP_PROP_FPS)
frame_count = int(vc.get(cv2.CAP_PROP_FRAME_COUNT))
#print(frame_count)
video = []

for idx in range(frame_count):
vc.set(1, idx)
ret, frame = vc.read()
height, width, layers = frame.shape
size = (width, height)

if frame is not None:
file_name = '{}{}{:04d}.jpg'.format(output_folder,a,idx+1)
cv2.imwrite(file_name, frame)

print("\rprocess: {}/{}".format(idx+1 , frame_count), end = '')
vc.release()
# ----------------------------------------
# 移動影片到資料夾
shutil.move(str(a)+'.mp4',str(a))

參考:【OpenCV】OpenCV 利用 python OpenCV 將一部影片拆成一張張圖片 sample code (內附程式碼) get images from video
詳閱:【永成的學習部落格】使用相機攝影截圖取AI辨識樣本
這一篇是我過去所寫的一篇文章。


訓練與驗證資料

準備資料時,先分開訓練集與驗證集:訓練集用來學習,驗證集用來觀察模型在未參與訓練的資料上的表現。

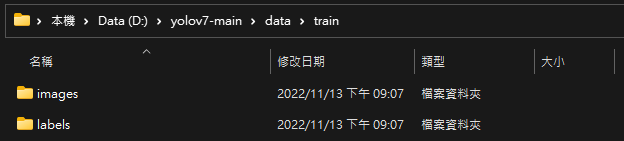
  1. 訓練模型
    增加資料時,要同時考慮圖片品質、標註一致性與實際場景的多樣性;重複或錯誤標註的圖片,不一定能改善模型。資料量增加也會影響訓練所需時間。
    依本篇配置,將圖片放在.\yolov5-master\data\train裡面
  • 示意圖:
    訓練與驗證資料:原文圖片 09


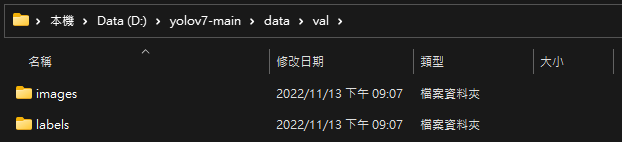
  1. 驗證模型
    原始練習以至少 20 張圖片作為驗證集起點,這不是所有任務都適用的最低門檻。實際張數應能涵蓋各類別與預期使用情境。
    依本篇配置,將圖片放在.\yolov5-master\data\val裡面
  • 示意圖:
    訓練與驗證資料:原文圖片 10


這裡以 7:3 或 8:2 作為資料切分比例的例子。切分後要確認驗證圖片沒有同時出現在訓練集中,避免結果過度樂觀。


模型訓練

準備自訂資料與模型設定

YOLOv5 進行自訂物件偵測時,需要讓圖片、標註與類別設定相互對應,才能依資料學習目標類別。

  1. 將.\yolov5-master\data\coco.yaml的檔案複製,將檔名取為custom_data.yaml,然後編輯檔案:

    1
    2
    3
    4
    5
    6
    7
    8
    train: ./data/train  # 訓練的圖片&labels的資料夾索引
    val: ./data/val # 驗證的圖片&labels的資料夾索引

    # number of classes # 數字為訓練圖片類別的數量
    nc: 1

    # class names
    names: [ 'bad' ] # 類別名稱的設置
  2. 將.\yolov5-master\models\yolov5s.yaml的檔案複製,將檔名取為yolov5s-custom.yaml,然後編輯檔案:

    1
    2
    3
    4
    # parameters
    nc: 1 # number of classes # 數字為訓練圖片類別的數量
    depth_multiple: 0.33 # model depth multiple # 模型深度倍數
    width_multiple: 0.25 # layer channel multiple # 層通道多
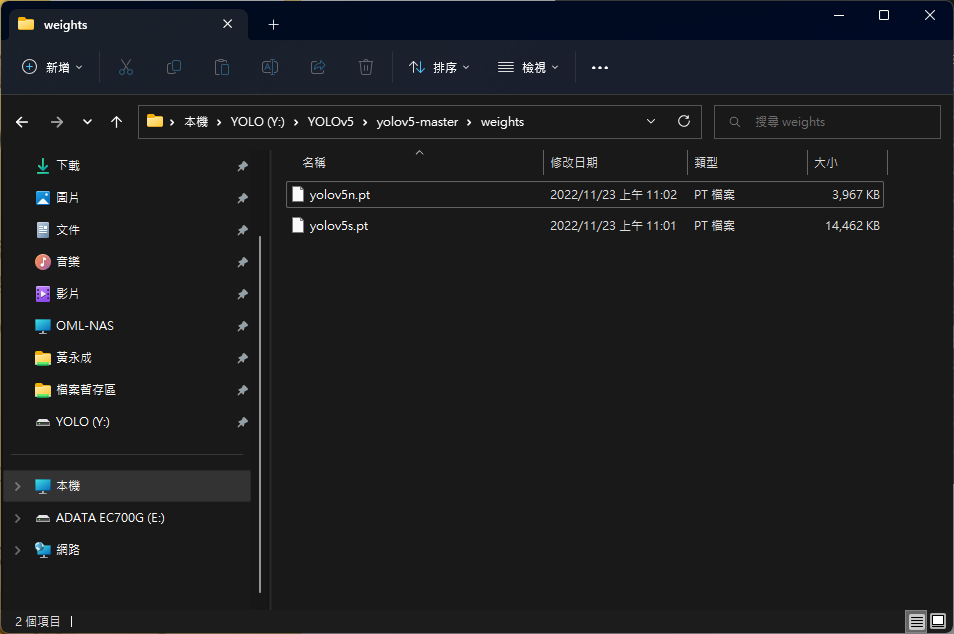
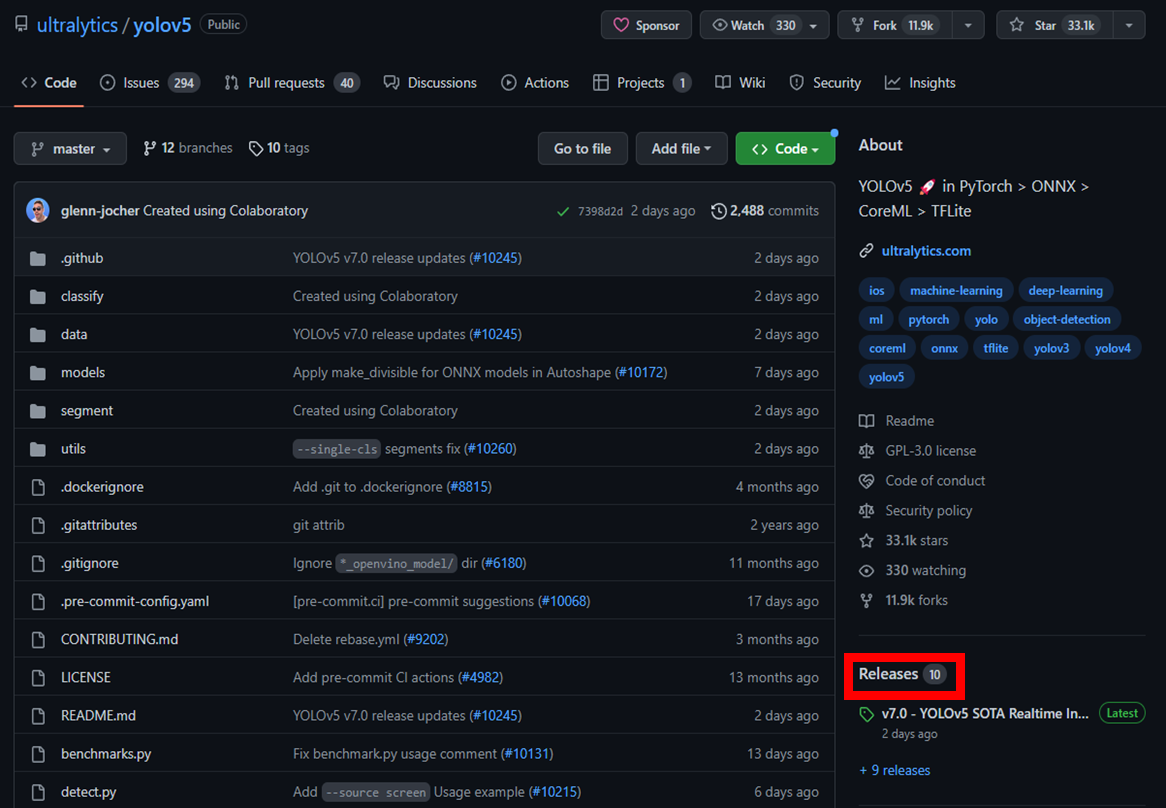
  3. 到YOLOv5-Github的Releases頁面下載預訓練權重。原筆記在此重複列出同一檔名(yolov5s.pt和yolov5s.pt),實際只需下載所選模型的權重,並存放在.\yolov5-master\weights目錄下:

    示意圖(點擊展開) 解決辦法: 訓練自定義數據:原文圖片 11

    (如果沒有.\yolov5-master\weights目錄,請自行建立一個weights目錄)
    下載連結:https://github.com/ultralytics/yolov5/releases/tag/v7.0

    訓練自定義數據:原文圖片 12


選擇型號

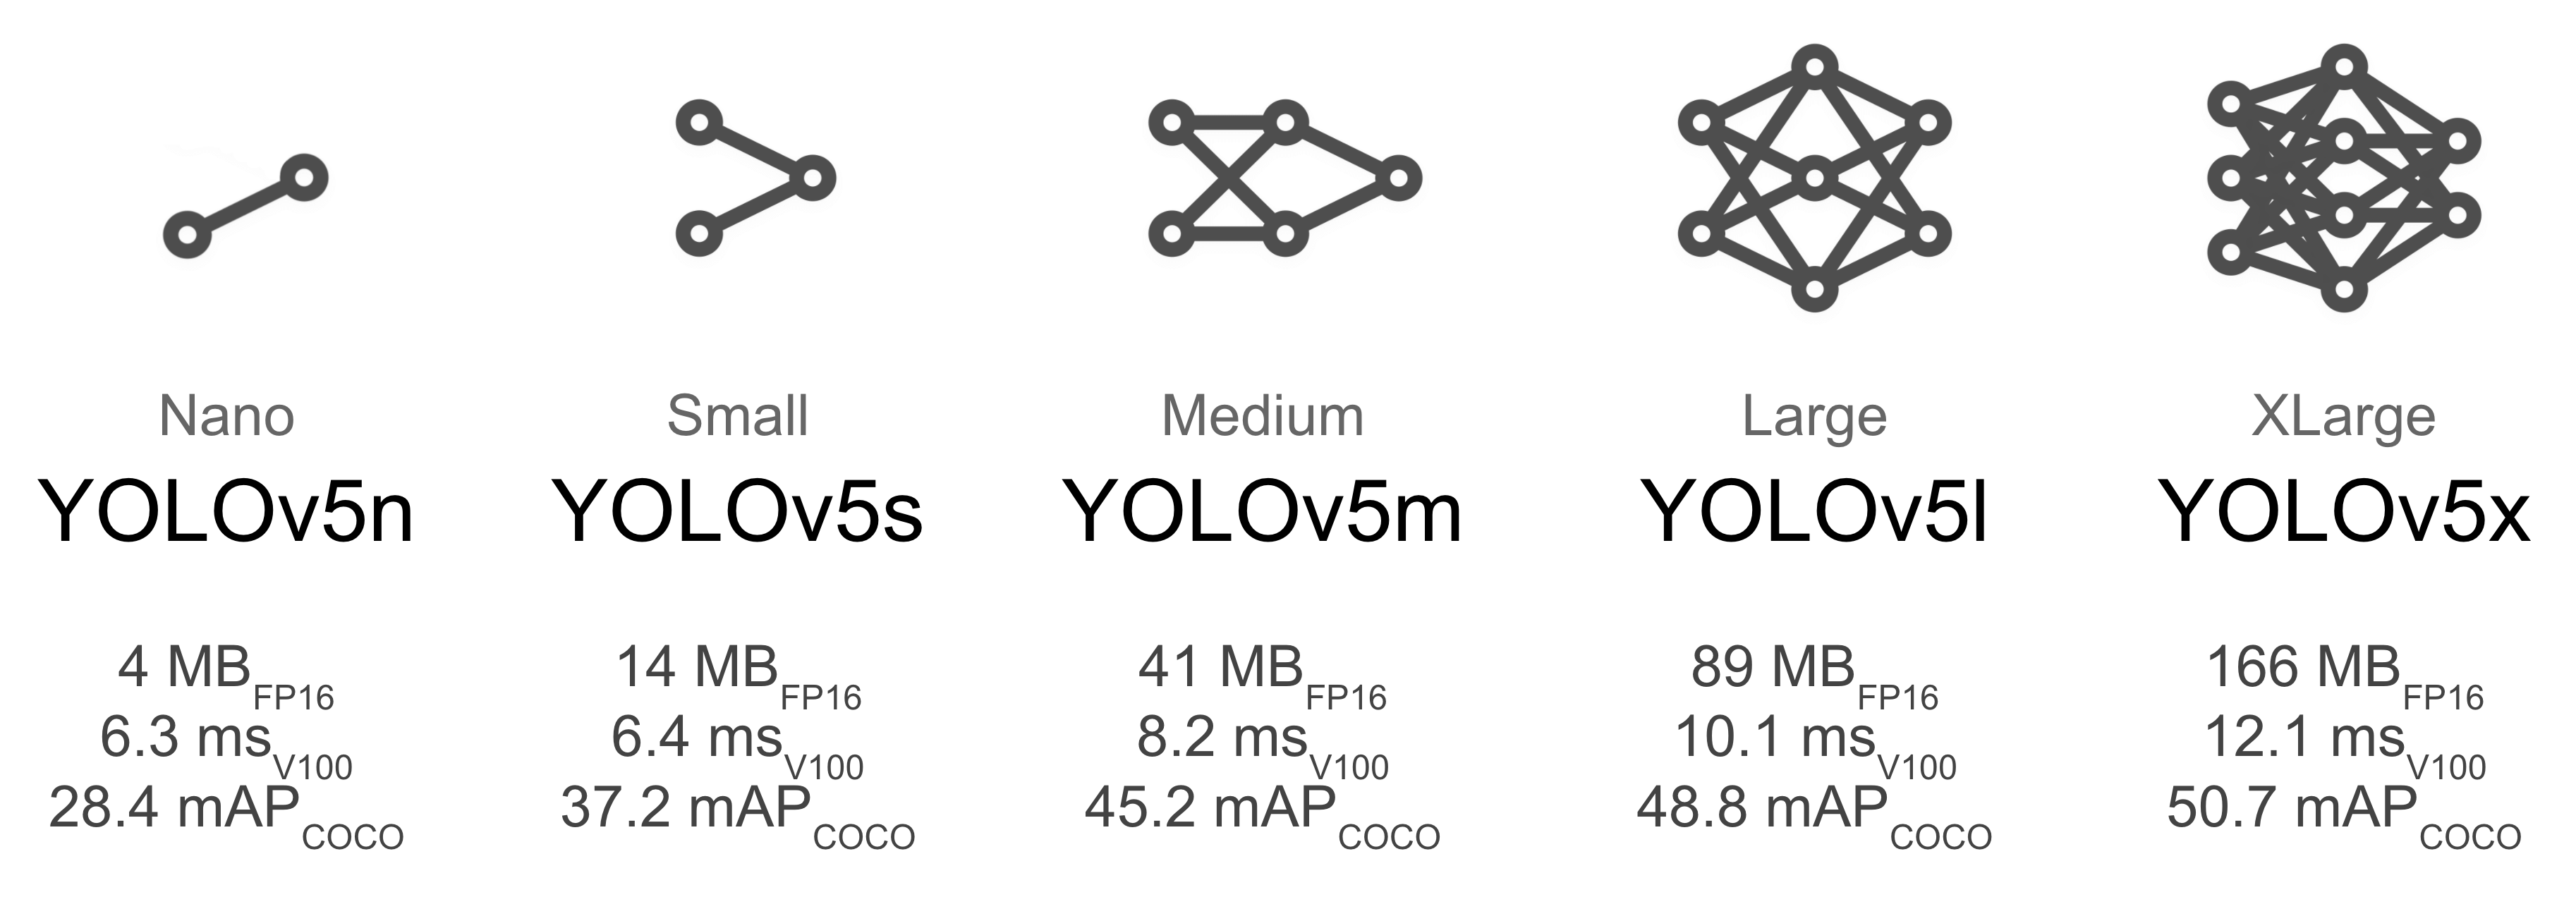
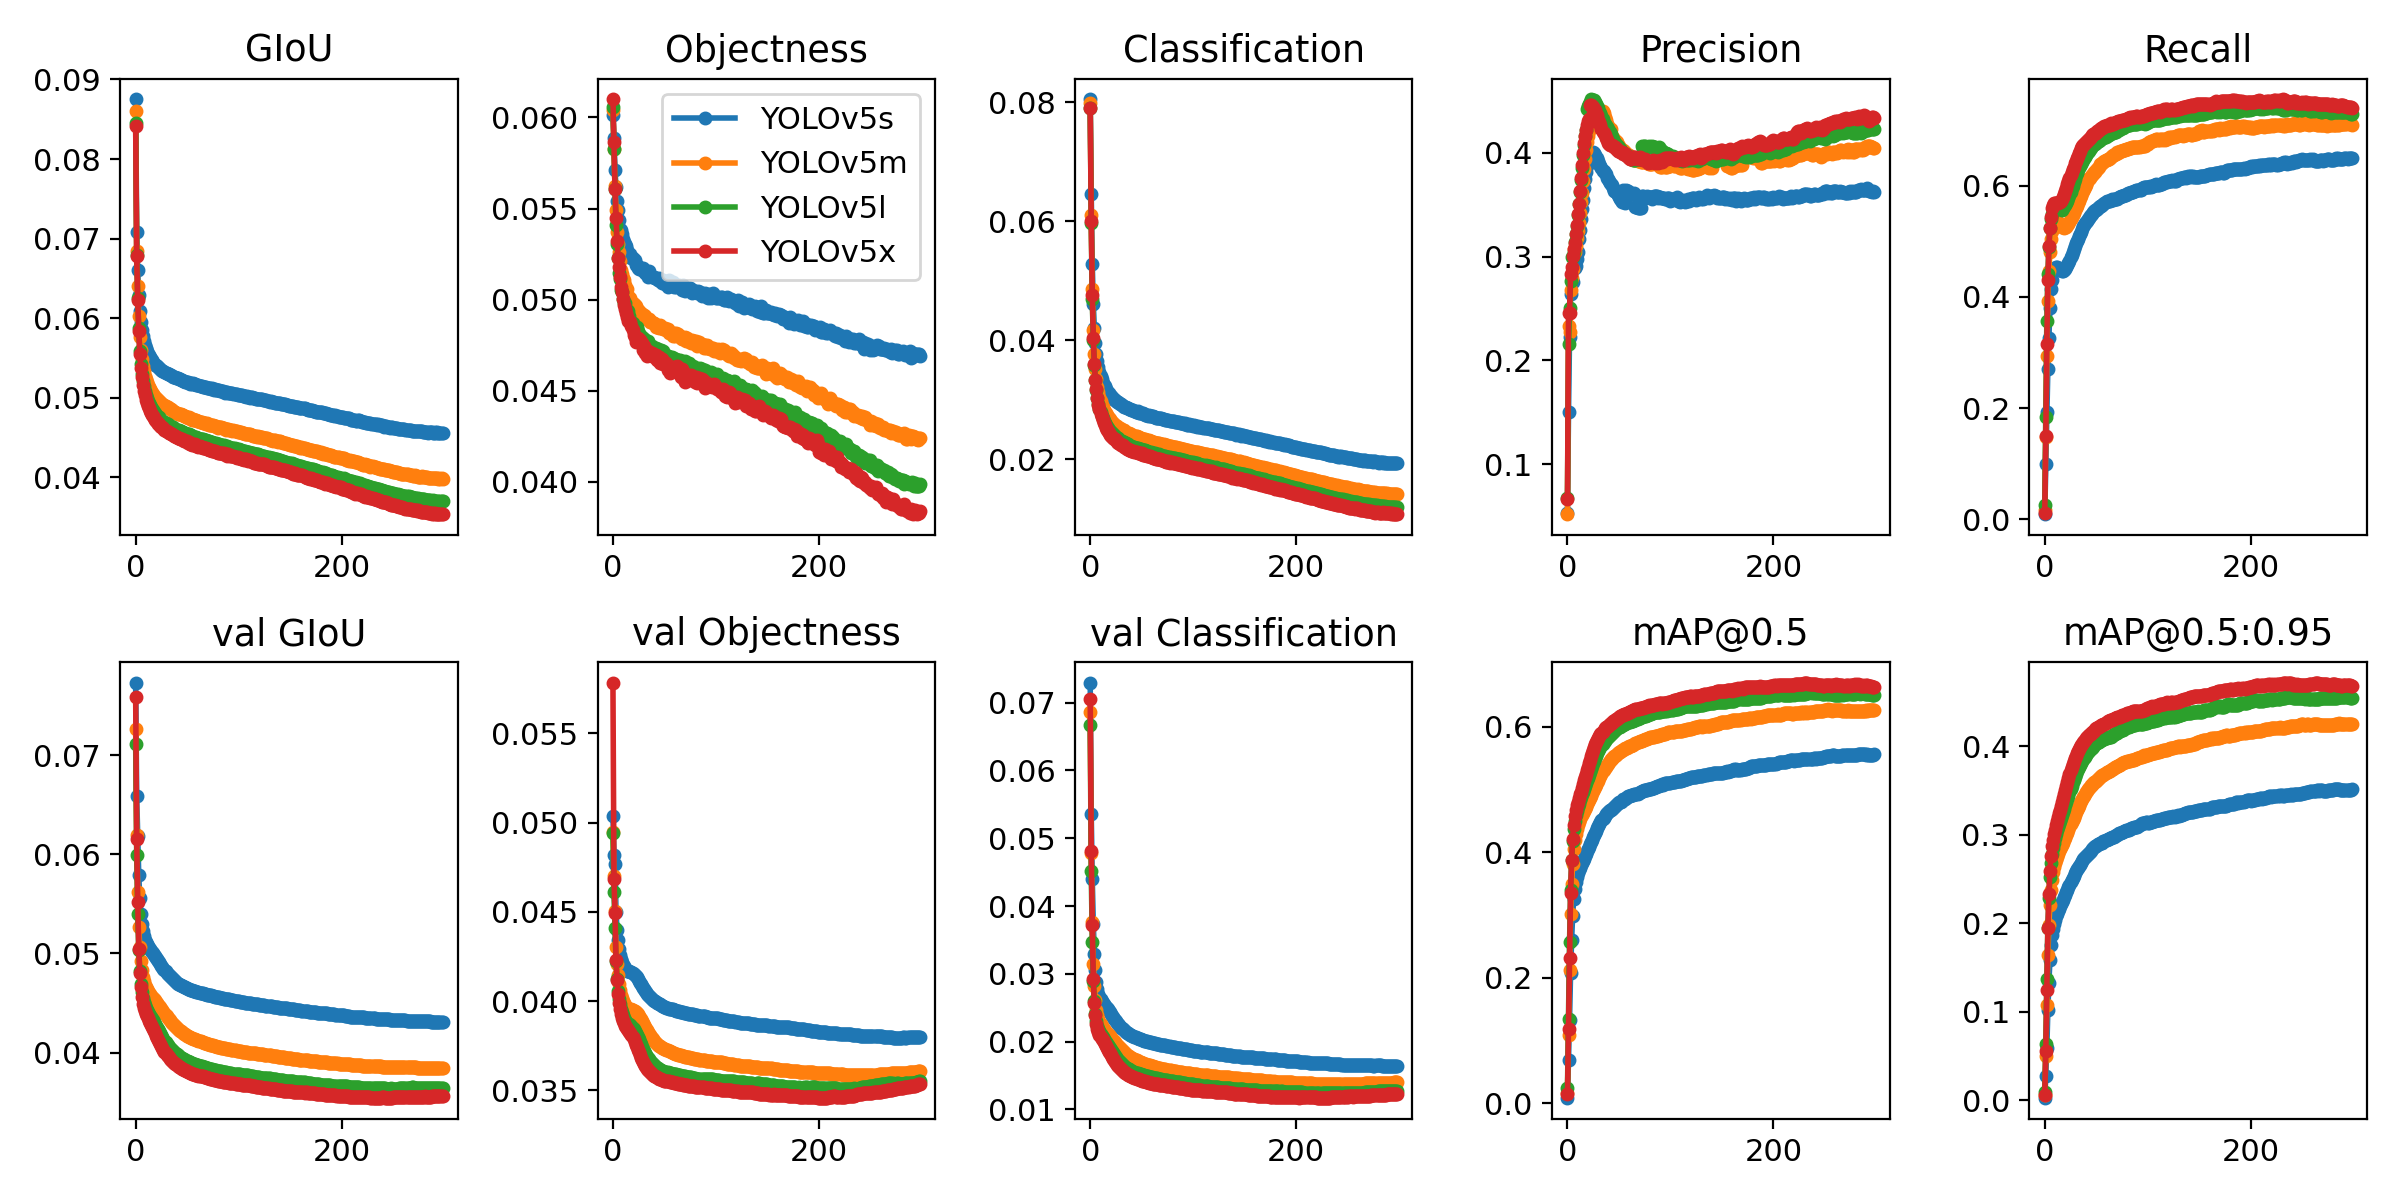
這份實作以 YOLOv5s 預訓練權重開始訓練。不同型號在速度、大小與表現之間有取捨,請配合自己的硬體與需求選擇。
模型型號的比較可查閱專案 README;不要把單一型號視為所有場景的最佳選擇。
選擇型號:原文圖片 13
選擇型號:原文圖片 14

開始訓練

1
python train.py --workers 1 --device 0 --imgsz 640 --data data/custom_data.yaml --hyp data/hyps/hyp.scratch-low.yaml --cfg models/yolov5s-custom.yaml --weights weights/yolov5s.pt --name train-run --project runs/train --batch-size 16 --epochs 300

epochs:
可先以 300 個 epoch 作為這份練習的起點,再觀察訓練與驗證結果;不是所有任務都應使用固定回合數。
需要延長訓練時,依驗證表現調整回合數,避免只因尚未達到某個數字就持續增加。
batch size:
batch size 受記憶體、模型與圖片尺寸限制,也可能影響訓練表現。先使用可穩定執行的設定,再依結果調整。
超參數:
超參數檔名與位置依專案版本而異,請查看 data/hyps 等目錄及 --hyp 的設定;原文 hpy.scratch.yaml 的拼字不宜直接照抄。先保留所用版本的預設設定,建立可比較的基準。
資料增強可增加訓練時的變化,但是否有幫助需由驗證結果判斷;過強的變化也可能不符合實際場景。
調整 loss 各項權重時,需理解其用途並控制其他條件,不應把降低某一項權重當成通用的過度擬合解法。

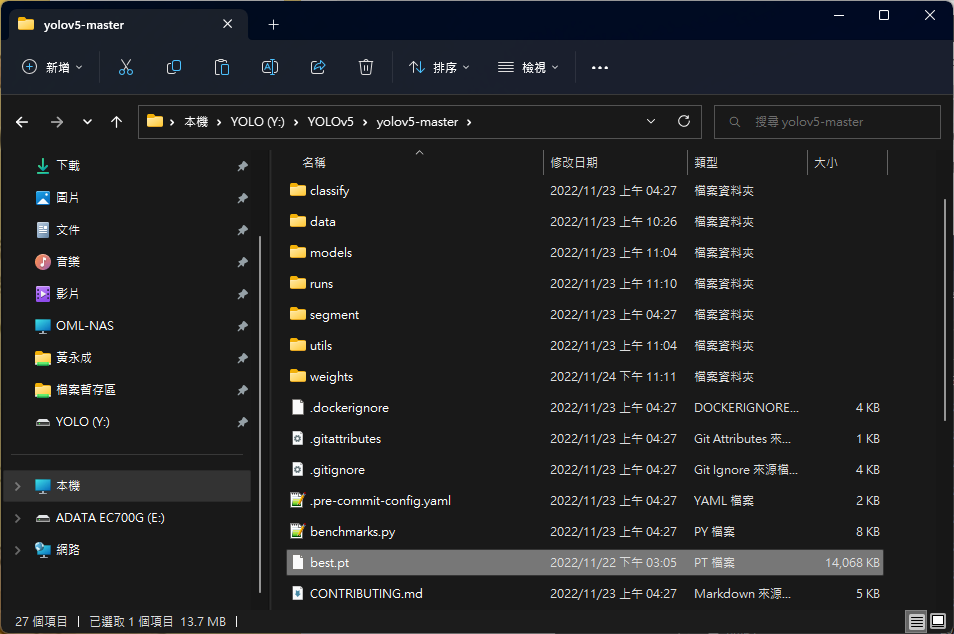
  • 若訓練完之後,將最新的.\runs\train的目錄下,
    yolov5s-train最新資料夾之.\weights\best.pt的檔案可依原範例複製到主目錄.\yolov5-master之下,或直接在偵測指令指定權重路徑。

    執行 detect 時,--weights 必須指向訓練產生的權重;原範例把檔案複製到主目錄只是方便使用相對路徑,也能直接指定原位置的 best.pt 檔案。

  • 如示意圖:
    開始訓練:原文圖片 15

    --weights:初始weights路徑。ex:--weights yolov5s.pt
    --cfg:model.yaml路徑。 ex:--cfg cfg/training/yolov5s-custom.yaml
    --data:data.yaml路徑。ex:--data data/custom_data.yaml
    --hyp:hyperparameters路徑。ex:--hyp data/hyp.scratch.custom.yaml
    --epochs:訓練回合,預設為100回合。ex:--epochs 200
    --batch-size:預設=16, 所有 GPU 的總批大小。ex:--batch-size 11
    --img-size:[訓練, 測試] 圖片大小,預設為【640,640】。ex:--img 640 640
    --workers:訓練資料讀取工作的最大數量。ex:--workers 1
    --name:將訓練結果資料夾名稱命名。ex:--name yolov5s-train
    --project:將訓練結果保存到自訂資料夾。ex:--project runs/train
    --device :指定運算裝置,例如 GPU 編號或 cpu。預設值請以所用腳本的 --help 為準;原文的 --cuda device 標示應對照實際 --device 參數。ex:--device 0

    • (查看更多指令說明):

      在 Anaconda Prompt (yolov5) 上輸入:

      1
      python train.py -h

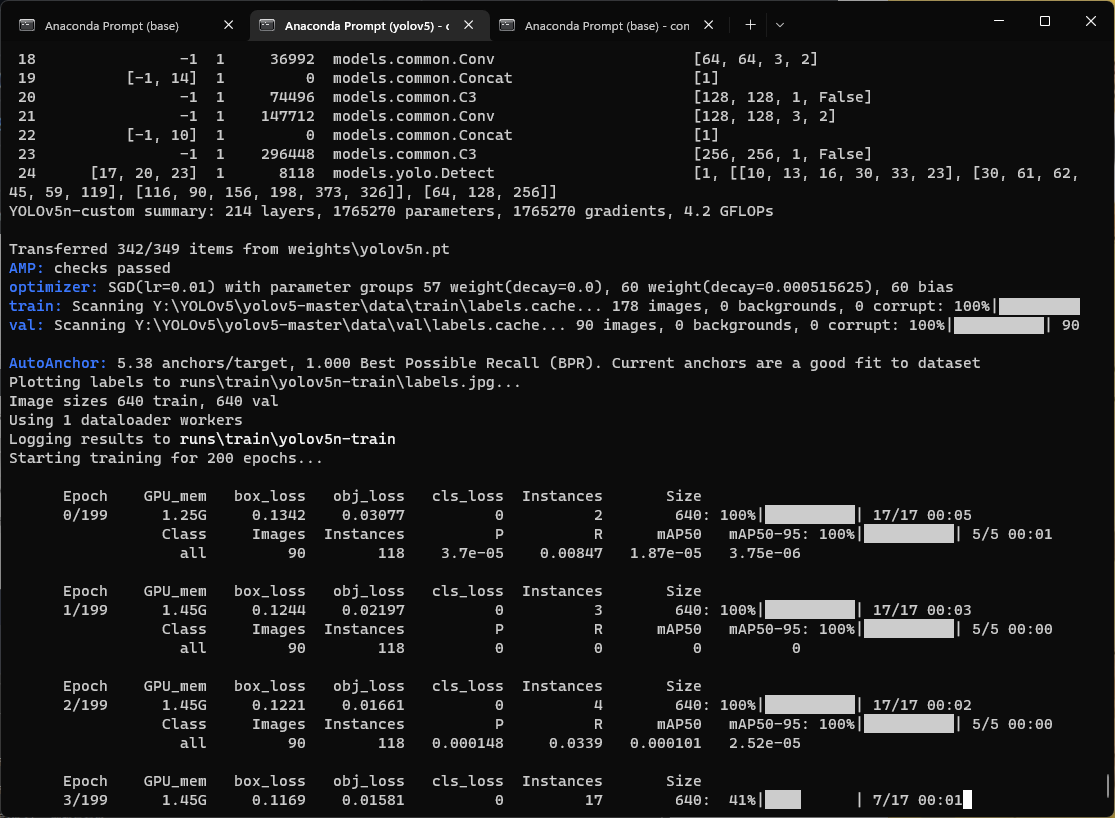
      ● 訓練過程,請耐心等候~
      開始訓練:原文圖片 16

train.py

train.py 中文修改補充(點擊展開)
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
43
44
45
46
47
48
49
50
51
52
53
54
55
56
57
58
59
60
61
62
63
64
65
66
67
68
69
70
71
72
73
74
75
76
77
78
79
80
81
82
83
84
85
86
87
88
89
90
91
92
93
94
95
96
97
98
99
100
101
102
103
104
105
106
107
108
109
110
111
112
113
114
115
116
117
118
119
120
121
122
123
124
125
126
127
128
129
130
131
132
133
134
135
136
137
138
139
140
141
142
143
144
145
146
147
148
149
150
151
152
153
154
155
156
157
158
159
160
161
162
163
164
165
166
167
168
169
170
171
172
173
174
175
176
177
178
179
180
181
182
183
184
185
186
187
188
189
190
191
192
193
194
195
196
197
198
199
200
201
202
203
204
205
206
207
208
209
210
211
212
213
214
215
216
217
218
219
220
221
222
223
224
225
226
227
228
229
230
231
232
233
234
235
236
237
238
239
240
241
242
243
244
245
246
247
248
249
250
251
252
253
254
255
256
257
258
259
260
261
262
263
264
265
266
267
268
269
270
271
272
273
274
275
276
277
278
279
280
281
282
283
284
285
286
287
288
289
290
291
292
293
294
295
296
297
298
299
300
301
302
303
304
305
306
307
308
309
310
311
312
313
314
315
316
317
318
319
320
321
322
323
324
325
326
327
328
329
330
331
332
333
334
335
336
337
338
339
340
341
342
343
344
345
346
347
348
349
350
351
352
353
354
355
356
357
358
359
360
361
362
363
364
365
366
367
368
369
370
371
372
373
374
375
376
377
378
379
380
381
382
383
384
385
386
387
388
389
390
391
392
393
394
395
396
397
398
399
400
401
402
403
404
405
406
407
408
409
410
411
412
413
414
415
416
417
418
419
420
421
422
423
424
425
426
427
428
429
430
431
432
433
434
435
436
437
438
439
440
441
442
443
444
445
446
447
448
449
450
451
452
453
454
455
456
457
458
459
460
461
462
463
464
465
466
467
468
469
470
471
472
473
474
475
476
477
478
479
480
481
482
483
484
485
486
487
488
489
490
491
492
493
494
495
496
497
498
499
500
501
502
503
504
505
506
507
508
509
510
511
512
513
514
515
516
517
518
519
520
521
522
523
524
525
526
527
528
529
530
531
532
533
534
535
536
537
538
539
540
541
542
543
544
545
546
547
548
549
550
551
552
553
554
555
556
557
558
559
560
561
562
563
564
565
566
567
568
569
570
571
572
573
574
575
576
577
578
579
580
581
582
583
584
585
586
587
588
589
590
591
592
593
594
595
596
597
598
599
600
601
602
603
604
605
606
607
608
609
610
611
612
613
614
615
616
617
618
619
620
621
622
623
624
625
626
627
628
629
630
631
632
633
# YOLOv5 🚀 by Ultralytics, GPL-3.0 license
"""
在自定義數據集上訓練 YOLOv5 模型。
從最新的 YOLOv5 版本自動下載模型和數據集。

用法 - 單 GPU 訓練:
$ python train.py --data coco128.yaml --weights yolov5s.pt --img 640 # from pretrained (recommended)
$ python train.py --data coco128.yaml --weights '' --cfg yolov5s.yaml --img 640 # from scratch

用法 - 多 GPU DDP 訓練:
$ python -m torch.distributed.run --nproc_per_node 4 --master_port 1 train.py --data coco128.yaml --weights yolov5s.pt --img 640 --device 0,1,2,3

模型: https://github.com/ultralytics/yolov5/tree/master/models
數據集: https://github.com/ultralytics/yolov5/tree/master/data
教程: https://github.com/ultralytics/yolov5/wiki/Train-Custom-Data
"""

import argparse
import math
import os
import random
import sys
import time
from copy import deepcopy
from datetime import datetime
from pathlib import Path

import numpy as np
import torch
import torch.distributed as dist
import torch.nn as nn
import yaml
from torch.optim import lr_scheduler
from tqdm import tqdm

FILE = Path(__file__).resolve()
ROOT = FILE.parents[0] # YOLOv5 root directory
if str(ROOT) not in sys.path:
sys.path.append(str(ROOT)) # add ROOT to PATH
ROOT = Path(os.path.relpath(ROOT, Path.cwd())) # relative

import val as validate # for end-of-epoch mAP
from models.experimental import attempt_load
from models.yolo import Model
from utils.autoanchor import check_anchors
from utils.autobatch import check_train_batch_size
from utils.callbacks import Callbacks
from utils.dataloaders import create_dataloader
from utils.downloads import attempt_download, is_url
from utils.general import (LOGGER, TQDM_BAR_FORMAT, check_amp, check_dataset, check_file, check_git_info,
check_git_status, check_img_size, check_requirements, check_suffix, check_yaml, colorstr,
get_latest_run, increment_path, init_seeds, intersect_dicts, labels_to_class_weights,
labels_to_image_weights, methods, one_cycle, print_args, print_mutation, strip_optimizer,
yaml_save)
from utils.loggers import Loggers
from utils.loggers.comet.comet_utils import check_comet_resume
from utils.loss import ComputeLoss
from utils.metrics import fitness
from utils.plots import plot_evolve
from utils.torch_utils import (EarlyStopping, ModelEMA, de_parallel, select_device, smart_DDP, smart_optimizer,
smart_resume, torch_distributed_zero_first)

LOCAL_RANK = int(os.getenv('LOCAL_RANK', -1)) # https://pytorch.org/docs/stable/elastic/run.html
RANK = int(os.getenv('RANK', -1))
WORLD_SIZE = int(os.getenv('WORLD_SIZE', 1))
GIT_INFO = check_git_info()


def train(hyp, opt, device, callbacks): # hyp is path/to/hyp.yaml or hyp dictionary
save_dir, epochs, batch_size, weights, single_cls, evolve, data, cfg, resume, noval, nosave, workers, freeze = \
Path(opt.save_dir), opt.epochs, opt.batch_size, opt.weights, opt.single_cls, opt.evolve, opt.data, opt.cfg, \
opt.resume, opt.noval, opt.nosave, opt.workers, opt.freeze
callbacks.run('on_pretrain_routine_start')

# Directories
w = save_dir / 'weights' # weights dir
(w.parent if evolve else w).mkdir(parents=True, exist_ok=True) # make dir
last, best = w / 'last.pt', w / 'best.pt'

# Hyperparameters
if isinstance(hyp, str):
with open(hyp, errors='ignore') as f:
hyp = yaml.safe_load(f) # load hyps dict
LOGGER.info(colorstr('hyperparameters: ') + ', '.join(f'{k}={v}' for k, v in hyp.items()))
opt.hyp = hyp.copy() # for saving hyps to checkpoints

# Save run settings
if not evolve:
yaml_save(save_dir / 'hyp.yaml', hyp)
yaml_save(save_dir / 'opt.yaml', vars(opt))

# Loggers
data_dict = None
if RANK in {-1, 0}:
loggers = Loggers(save_dir, weights, opt, hyp, LOGGER) # loggers instance

# Register actions
for k in methods(loggers):
callbacks.register_action(k, callback=getattr(loggers, k))

# Process custom dataset artifact link
data_dict = loggers.remote_dataset
if resume: # If resuming runs from remote artifact
weights, epochs, hyp, batch_size = opt.weights, opt.epochs, opt.hyp, opt.batch_size

# Config
plots = not evolve and not opt.noplots # create plots
cuda = device.type != 'cpu'
init_seeds(opt.seed + 1 + RANK, deterministic=True)
with torch_distributed_zero_first(LOCAL_RANK):
data_dict = data_dict or check_dataset(data) # check if None
train_path, val_path = data_dict['train'], data_dict['val']
nc = 1 if single_cls else int(data_dict['nc']) # number of classes
names = {0: 'item'} if single_cls and len(data_dict['names']) != 1 else data_dict['names'] # class names
is_coco = isinstance(val_path, str) and val_path.endswith('coco/val2017.txt') # COCO dataset

# Model
check_suffix(weights, '.pt') # check weights
pretrained = weights.endswith('.pt')
if pretrained:
with torch_distributed_zero_first(LOCAL_RANK):
weights = attempt_download(weights) # download if not found locally
ckpt = torch.load(weights, map_location='cpu') # load checkpoint to CPU to avoid CUDA memory leak
model = Model(cfg or ckpt['model'].yaml, ch=3, nc=nc, anchors=hyp.get('anchors')).to(device) # create
exclude = ['anchor'] if (cfg or hyp.get('anchors')) and not resume else [] # exclude keys
csd = ckpt['model'].float().state_dict() # checkpoint state_dict as FP32
csd = intersect_dicts(csd, model.state_dict(), exclude=exclude) # intersect
model.load_state_dict(csd, strict=False) # load
LOGGER.info(f'Transferred {len(csd)}/{len(model.state_dict())} items from {weights}') # report
else:
model = Model(cfg, ch=3, nc=nc, anchors=hyp.get('anchors')).to(device) # create
amp = check_amp(model) # check AMP

# Freeze
freeze = [f'model.{x}.' for x in (freeze if len(freeze) > 1 else range(freeze[0]))] # layers to freeze
for k, v in model.named_parameters():
v.requires_grad = True # train all layers
# v.register_hook(lambda x: torch.nan_to_num(x)) # NaN to 0 (commented for erratic training results)
if any(x in k for x in freeze):
LOGGER.info(f'freezing {k}')
v.requires_grad = False

# Image size
gs = max(int(model.stride.max()), 32) # grid size (max stride)
imgsz = check_img_size(opt.imgsz, gs, floor=gs * 2) # verify imgsz is gs-multiple

# Batch size
if RANK == -1 and batch_size == -1: # single-GPU only, estimate best batch size
batch_size = check_train_batch_size(model, imgsz, amp)
loggers.on_params_update({"batch_size": batch_size})

# Optimizer
nbs = 64 # nominal batch size
accumulate = max(round(nbs / batch_size), 1) # accumulate loss before optimizing
hyp['weight_decay'] *= batch_size * accumulate / nbs # scale weight_decay
optimizer = smart_optimizer(model, opt.optimizer, hyp['lr0'], hyp['momentum'], hyp['weight_decay'])

# Scheduler
if opt.cos_lr:
lf = one_cycle(1, hyp['lrf'], epochs) # cosine 1->hyp['lrf']
else:
lf = lambda x: (1 - x / epochs) * (1.0 - hyp['lrf']) + hyp['lrf'] # linear
scheduler = lr_scheduler.LambdaLR(optimizer, lr_lambda=lf) # plot_lr_scheduler(optimizer, scheduler, epochs)

# EMA
ema = ModelEMA(model) if RANK in {-1, 0} else None

# Resume
best_fitness, start_epoch = 0.0, 0
if pretrained:
if resume:
best_fitness, start_epoch, epochs = smart_resume(ckpt, optimizer, ema, weights, epochs, resume)
del ckpt, csd

# DP mode
if cuda and RANK == -1 and torch.cuda.device_count() > 1:
LOGGER.warning('WARNING ⚠️ DP not recommended, use torch.distributed.run for best DDP Multi-GPU results.\n'
'See Multi-GPU Tutorial at https://github.com/ultralytics/yolov5/issues/475 to get started.')
model = torch.nn.DataParallel(model)

# SyncBatchNorm
if opt.sync_bn and cuda and RANK != -1:
model = torch.nn.SyncBatchNorm.convert_sync_batchnorm(model).to(device)
LOGGER.info('Using SyncBatchNorm()')

# Trainloader
train_loader, dataset = create_dataloader(train_path,
imgsz,
batch_size // WORLD_SIZE,
gs,
single_cls,
hyp=hyp,
augment=True,
cache=None if opt.cache == 'val' else opt.cache,
rect=opt.rect,
rank=LOCAL_RANK,
workers=workers,
image_weights=opt.image_weights,
quad=opt.quad,
prefix=colorstr('train: '),
shuffle=True)
labels = np.concatenate(dataset.labels, 0)
mlc = int(labels[:, 0].max()) # max label class
assert mlc < nc, f'Label class {mlc} exceeds nc={nc} in {data}. Possible class labels are 0-{nc - 1}'

# Process 0
if RANK in {-1, 0}:
val_loader = create_dataloader(val_path,
imgsz,
batch_size // WORLD_SIZE * 2,
gs,
single_cls,
hyp=hyp,
cache=None if noval else opt.cache,
rect=True,
rank=-1,
workers=workers * 2,
pad=0.5,
prefix=colorstr('val: '))[0]

if not resume:
if not opt.noautoanchor:
check_anchors(dataset, model=model, thr=hyp['anchor_t'], imgsz=imgsz) # run AutoAnchor
model.half().float() # pre-reduce anchor precision

callbacks.run('on_pretrain_routine_end', labels, names)

# DDP mode
if cuda and RANK != -1:
model = smart_DDP(model)

# Model attributes
nl = de_parallel(model).model[-1].nl # number of detection layers (to scale hyps)
hyp['box'] *= 3 / nl # scale to layers
hyp['cls'] *= nc / 80 * 3 / nl # scale to classes and layers
hyp['obj'] *= (imgsz / 640) ** 2 * 3 / nl # scale to image size and layers
hyp['label_smoothing'] = opt.label_smoothing
model.nc = nc # attach number of classes to model
model.hyp = hyp # attach hyperparameters to model
model.class_weights = labels_to_class_weights(dataset.labels, nc).to(device) * nc # attach class weights
model.names = names

# Start training
t0 = time.time()
nb = len(train_loader) # number of batches
nw = max(round(hyp['warmup_epochs'] * nb), 100) # number of warmup iterations, max(3 epochs, 100 iterations)
# nw = min(nw, (epochs - start_epoch) / 2 * nb) # limit warmup to < 1/2 of training
last_opt_step = -1
maps = np.zeros(nc) # mAP per class
results = (0, 0, 0, 0, 0, 0, 0) # P, R, mAP@.5, mAP@.5-.95, val_loss(box, obj, cls)
scheduler.last_epoch = start_epoch - 1 # do not move
scaler = torch.cuda.amp.GradScaler(enabled=amp)
stopper, stop = EarlyStopping(patience=opt.patience), False
compute_loss = ComputeLoss(model) # init loss class
callbacks.run('on_train_start')
LOGGER.info(f'Image sizes {imgsz} train, {imgsz} val\n'
f'Using {train_loader.num_workers * WORLD_SIZE} dataloader workers\n'
f"Logging results to {colorstr('bold', save_dir)}\n"
f'Starting training for {epochs} epochs...')
for epoch in range(start_epoch, epochs): # epoch ------------------------------------------------------------------
callbacks.run('on_train_epoch_start')
model.train()

# Update image weights (optional, single-GPU only)
if opt.image_weights:
cw = model.class_weights.cpu().numpy() * (1 - maps) ** 2 / nc # class weights
iw = labels_to_image_weights(dataset.labels, nc=nc, class_weights=cw) # image weights
dataset.indices = random.choices(range(dataset.n), weights=iw, k=dataset.n) # rand weighted idx

# Update mosaic border (optional)
# b = int(random.uniform(0.25 * imgsz, 0.75 * imgsz + gs) // gs * gs)
# dataset.mosaic_border = [b - imgsz, -b] # height, width borders

mloss = torch.zeros(3, device=device) # mean losses
if RANK != -1:
train_loader.sampler.set_epoch(epoch)
pbar = enumerate(train_loader)
LOGGER.info(('\n' + '%11s' * 7) % ('Epoch', 'GPU_mem', 'box_loss', 'obj_loss', 'cls_loss', 'Instances', 'Size'))
if RANK in {-1, 0}:
pbar = tqdm(pbar, total=nb, bar_format=TQDM_BAR_FORMAT) # progress bar
optimizer.zero_grad()
for i, (imgs, targets, paths, _) in pbar: # batch -------------------------------------------------------------
callbacks.run('on_train_batch_start')
ni = i + nb * epoch # number integrated batches (since train start)
imgs = imgs.to(device, non_blocking=True).float() / 255 # uint8 to float32, 0-255 to 0.0-1.0

# Warmup
if ni <= nw:
xi = [0, nw] # x interp
# compute_loss.gr = np.interp(ni, xi, [0.0, 1.0]) # iou loss ratio (obj_loss = 1.0 or iou)
accumulate = max(1, np.interp(ni, xi, [1, nbs / batch_size]).round())
for j, x in enumerate(optimizer.param_groups):
# bias lr falls from 0.1 to lr0, all other lrs rise from 0.0 to lr0
x['lr'] = np.interp(ni, xi, [hyp['warmup_bias_lr'] if j == 0 else 0.0, x['initial_lr'] * lf(epoch)])
if 'momentum' in x:
x['momentum'] = np.interp(ni, xi, [hyp['warmup_momentum'], hyp['momentum']])

# Multi-scale
if opt.multi_scale:
sz = random.randrange(imgsz * 0.5, imgsz * 1.5 + gs) // gs * gs # size
sf = sz / max(imgs.shape[2:]) # scale factor
if sf != 1:
ns = [math.ceil(x * sf / gs) * gs for x in imgs.shape[2:]] # new shape (stretched to gs-multiple)
imgs = nn.functional.interpolate(imgs, size=ns, mode='bilinear', align_corners=False)

# Forward
with torch.cuda.amp.autocast(amp):
pred = model(imgs) # forward
loss, loss_items = compute_loss(pred, targets.to(device)) # loss scaled by batch_size
if RANK != -1:
loss *= WORLD_SIZE # gradient averaged between devices in DDP mode
if opt.quad:
loss *= 4.

# Backward
scaler.scale(loss).backward()

# Optimize - https://pytorch.org/docs/master/notes/amp_examples.html
if ni - last_opt_step >= accumulate:
scaler.unscale_(optimizer) # unscale gradients
torch.nn.utils.clip_grad_norm_(model.parameters(), max_norm=10.0) # clip gradients
scaler.step(optimizer) # optimizer.step
scaler.update()
optimizer.zero_grad()
if ema:
ema.update(model)
last_opt_step = ni

# Log
if RANK in {-1, 0}:
mloss = (mloss * i + loss_items) / (i + 1) # update mean losses
mem = f'{torch.cuda.memory_reserved() / 1E9 if torch.cuda.is_available() else 0:.3g}G' # (GB)
pbar.set_description(('%11s' * 2 + '%11.4g' * 5) %
(f'{epoch}/{epochs - 1}', mem, *mloss, targets.shape[0], imgs.shape[-1]))
callbacks.run('on_train_batch_end', model, ni, imgs, targets, paths, list(mloss))
if callbacks.stop_training:
return
# end batch ------------------------------------------------------------------------------------------------

# Scheduler
lr = [x['lr'] for x in optimizer.param_groups] # for loggers
scheduler.step()

if RANK in {-1, 0}:
# mAP
callbacks.run('on_train_epoch_end', epoch=epoch)
ema.update_attr(model, include=['yaml', 'nc', 'hyp', 'names', 'stride', 'class_weights'])
final_epoch = (epoch + 1 == epochs) or stopper.possible_stop
if not noval or final_epoch: # Calculate mAP
results, maps, _ = validate.run(data_dict,
batch_size=batch_size // WORLD_SIZE * 2,
imgsz=imgsz,
half=amp,
model=ema.ema,
single_cls=single_cls,
dataloader=val_loader,
save_dir=save_dir,
plots=False,
callbacks=callbacks,
compute_loss=compute_loss)

# Update best mAP
fi = fitness(np.array(results).reshape(1, -1)) # weighted combination of [P, R, mAP@.5, mAP@.5-.95]
stop = stopper(epoch=epoch, fitness=fi) # early stop check
if fi > best_fitness:
best_fitness = fi
log_vals = list(mloss) + list(results) + lr
callbacks.run('on_fit_epoch_end', log_vals, epoch, best_fitness, fi)

# Save model
if (not nosave) or (final_epoch and not evolve): # if save
ckpt = {
'epoch': epoch,
'best_fitness': best_fitness,
'model': deepcopy(de_parallel(model)).half(),
'ema': deepcopy(ema.ema).half(),
'updates': ema.updates,
'optimizer': optimizer.state_dict(),
'opt': vars(opt),
'git': GIT_INFO, # {remote, branch, commit} if a git repo
'date': datetime.now().isoformat()}

# Save last, best and delete
torch.save(ckpt, last)
if best_fitness == fi:
torch.save(ckpt, best)
if opt.save_period > 0 and epoch % opt.save_period == 0:
torch.save(ckpt, w / f'epoch{epoch}.pt')
del ckpt
callbacks.run('on_model_save', last, epoch, final_epoch, best_fitness, fi)

# EarlyStopping
if RANK != -1: # if DDP training
broadcast_list = [stop if RANK == 0 else None]
dist.broadcast_object_list(broadcast_list, 0) # broadcast 'stop' to all ranks
if RANK != 0:
stop = broadcast_list[0]
if stop:
break # must break all DDP ranks

# end epoch ----------------------------------------------------------------------------------------------------
# end training -----------------------------------------------------------------------------------------------------
if RANK in {-1, 0}:
LOGGER.info(f'\n{epoch - start_epoch + 1} epochs completed in {(time.time() - t0) / 3600:.3f} hours.')
for f in last, best:
if f.exists():
strip_optimizer(f) # strip optimizers
if f is best:
LOGGER.info(f'\nValidating {f}...')
results, _, _ = validate.run(
data_dict,
batch_size=batch_size // WORLD_SIZE * 2,
imgsz=imgsz,
model=attempt_load(f, device).half(),
iou_thres=0.65 if is_coco else 0.60, # best pycocotools at iou 0.65
single_cls=single_cls,
dataloader=val_loader,
save_dir=save_dir,
save_json=is_coco,
verbose=True,
plots=plots,
callbacks=callbacks,
compute_loss=compute_loss) # val best model with plots
if is_coco:
callbacks.run('on_fit_epoch_end', list(mloss) + list(results) + lr, epoch, best_fitness, fi)

callbacks.run('on_train_end', last, best, epoch, results)

torch.cuda.empty_cache()
return results


def parse_opt(known=False):
parser = argparse.ArgumentParser()
parser.add_argument('--weights', type=str, default=ROOT / 'yolov5s.pt', help='初始 weights 路徑')
parser.add_argument('--cfg', type=str, default='', help='model.yaml 路徑')
parser.add_argument('--data', type=str, default=ROOT / 'data/coco128.yaml', help='dataset.yaml 路徑')
parser.add_argument('--hyp', type=str, default=ROOT / 'data/hyps/hyp.scratch-low.yaml', help='hyperparameters 路徑')
parser.add_argument('--epochs', type=int, default=100, help='總訓練時期')
parser.add_argument('--batch-size', type=int, default=16, help='所有 GPU 的總批次大小,-1 表示自動批次')
parser.add_argument('--imgsz', '--img', '--img-size', type=int, default=640, help='train, val 圖像大小(像素)')
parser.add_argument('--rect', action='store_true', help='矩形訓練')
parser.add_argument('--resume', nargs='?', const=True, default=False, help='恢復最近的訓練')
parser.add_argument('--nosave', action='store_true', help='只保存最後的檢查點')
parser.add_argument('--noval', action='store_true', help='只驗證最終epoch')
parser.add_argument('--noautoanchor', action='store_true', help='禁用自動錨點')
parser.add_argument('--noplots', action='store_true', help='不保存繪圖文件')
parser.add_argument('--evolve', type=int, nargs='?', const=300, help='evolve hyperparameters for x generations')
parser.add_argument('--bucket', type=str, default='', help='gsutil bucket')
parser.add_argument('--cache', type=str, nargs='?', const='ram', help='圖像--緩存內存/磁盤')
parser.add_argument('--image-weights', action='store_true', help='使用weighted圖像選擇進行訓練')
parser.add_argument('--device', default='', help='cuda 設備,即 0 或 0,1,2,3 或 cpu')
parser.add_argument('--multi-scale', action='store_true', help='vary img-size +/- 50%%')
parser.add_argument('--single-cls', action='store_true', help='將多類數據訓練為單類')
parser.add_argument('--optimizer', type=str, choices=['SGD', 'Adam', 'AdamW'], default='SGD', help='優化器')
parser.add_argument('--sync-bn', action='store_true', help='使用 SyncBatchNorm,僅在 DDP 模式下可用')
parser.add_argument('--workers', type=int, default=8, help='最大數據加載器工作人員(在 DDP 模式下按 RANK)')
parser.add_argument('--project', default=ROOT / 'runs/train', help='保存到項目/名稱')
parser.add_argument('--name', default='exp', help='保存到項目/名稱')
parser.add_argument('--exist-ok', action='store_true', help='現有項目/名稱OK,不要增加')
parser.add_argument('--quad', action='store_true', help='quad dataloader')
parser.add_argument('--cos-lr', action='store_true', help='cosine LR scheduler')
parser.add_argument('--label-smoothing', type=float, default=0.0, help='Label smoothing epsilon')
parser.add_argument('--patience', type=int, default=100, help='EarlyStopping patience (epochs without improvement)')
parser.add_argument('--freeze', nargs='+', type=int, default=[0], help='Freeze layers: backbone=10, first3=0 1 2')
parser.add_argument('--save-period', type=int, default=-1, help='Save checkpoint every x epochs (disabled if < 1)')
parser.add_argument('--seed', type=int, default=0, help='Global training seed')
parser.add_argument('--local_rank', type=int, default=-1, help='自動 DDP Multi-GPU 參數,請勿修改')

# 記錄器參數
parser.add_argument('--entity', default=None, help='實體')
parser.add_argument('--upload_dataset', nargs='?', const=True, default=False, help='上傳數據,“val”選項')
parser.add_argument('--bbox_interval', type=int, default=-1, help='設置邊界框圖像記錄間隔')
parser.add_argument('--artifact_alias', type=str, default='latest', help='要使用的數據集工件版本')

return parser.parse_known_args()[0] if known else parser.parse_args()


def main(opt, callbacks=Callbacks()):
# Checks
if RANK in {-1, 0}:
print_args(vars(opt))
check_git_status()
check_requirements()

# Resume (from specified or most recent last.pt)
if opt.resume and not check_comet_resume(opt) and not opt.evolve:
last = Path(check_file(opt.resume) if isinstance(opt.resume, str) else get_latest_run())
opt_yaml = last.parent.parent / 'opt.yaml' # train options yaml
opt_data = opt.data # original dataset
if opt_yaml.is_file():
with open(opt_yaml, errors='ignore') as f:
d = yaml.safe_load(f)
else:
d = torch.load(last, map_location='cpu')['opt']
opt = argparse.Namespace(**d) # replace
opt.cfg, opt.weights, opt.resume = '', str(last), True # reinstate
if is_url(opt_data):
opt.data = check_file(opt_data) # avoid HUB resume auth timeout
else:
opt.data, opt.cfg, opt.hyp, opt.weights, opt.project = \
check_file(opt.data), check_yaml(opt.cfg), check_yaml(opt.hyp), str(opt.weights), str(opt.project) # checks
assert len(opt.cfg) or len(opt.weights), 'either --cfg or --weights must be specified'
if opt.evolve:
if opt.project == str(ROOT / 'runs/train'): # if default project name, rename to runs/evolve
opt.project = str(ROOT / 'runs/evolve')
opt.exist_ok, opt.resume = opt.resume, False # pass resume to exist_ok and disable resume
if opt.name == 'cfg':
opt.name = Path(opt.cfg).stem # use model.yaml as name
opt.save_dir = str(increment_path(Path(opt.project) / opt.name, exist_ok=opt.exist_ok))

# DDP mode
device = select_device(opt.device, batch_size=opt.batch_size)
if LOCAL_RANK != -1:
msg = 'is not compatible with YOLOv5 Multi-GPU DDP training'
assert not opt.image_weights, f'--image-weights {msg}'
assert not opt.evolve, f'--evolve {msg}'
assert opt.batch_size != -1, f'AutoBatch with --batch-size -1 {msg}, please pass a valid --batch-size'
assert opt.batch_size % WORLD_SIZE == 0, f'--batch-size {opt.batch_size} must be multiple of WORLD_SIZE'
assert torch.cuda.device_count() > LOCAL_RANK, 'insufficient CUDA devices for DDP command'
torch.cuda.set_device(LOCAL_RANK)
device = torch.device('cuda', LOCAL_RANK)
dist.init_process_group(backend="nccl" if dist.is_nccl_available() else "gloo")

# Train
if not opt.evolve:
train(opt.hyp, opt, device, callbacks)

# Evolve hyperparameters (optional)
else:
# Hyperparameter evolution metadata (mutation scale 0-1, lower_limit, upper_limit)
meta = {
'lr0': (1, 1e-5, 1e-1), # initial learning rate (SGD=1E-2, Adam=1E-3)
'lrf': (1, 0.01, 1.0), # final OneCycleLR learning rate (lr0 * lrf)
'momentum': (0.3, 0.6, 0.98), # SGD momentum/Adam beta1
'weight_decay': (1, 0.0, 0.001), # optimizer weight decay
'warmup_epochs': (1, 0.0, 5.0), # warmup epochs (fractions ok)
'warmup_momentum': (1, 0.0, 0.95), # warmup initial momentum
'warmup_bias_lr': (1, 0.0, 0.2), # warmup initial bias lr
'box': (1, 0.02, 0.2), # box loss gain
'cls': (1, 0.2, 4.0), # cls loss gain
'cls_pw': (1, 0.5, 2.0), # cls BCELoss positive_weight
'obj': (1, 0.2, 4.0), # obj loss gain (scale with pixels)
'obj_pw': (1, 0.5, 2.0), # obj BCELoss positive_weight
'iou_t': (0, 0.1, 0.7), # IoU training threshold
'anchor_t': (1, 2.0, 8.0), # anchor-multiple threshold
'anchors': (2, 2.0, 10.0), # anchors per output grid (0 to ignore)
'fl_gamma': (0, 0.0, 2.0), # focal loss gamma (efficientDet default gamma=1.5)
'hsv_h': (1, 0.0, 0.1), # image HSV-Hue augmentation (fraction)
'hsv_s': (1, 0.0, 0.9), # image HSV-Saturation augmentation (fraction)
'hsv_v': (1, 0.0, 0.9), # image HSV-Value augmentation (fraction)
'degrees': (1, 0.0, 45.0), # image rotation (+/- deg)
'translate': (1, 0.0, 0.9), # image translation (+/- fraction)
'scale': (1, 0.0, 0.9), # image scale (+/- gain)
'shear': (1, 0.0, 10.0), # image shear (+/- deg)
'perspective': (0, 0.0, 0.001), # image perspective (+/- fraction), range 0-0.001
'flipud': (1, 0.0, 1.0), # image flip up-down (probability)
'fliplr': (0, 0.0, 1.0), # image flip left-right (probability)
'mosaic': (1, 0.0, 1.0), # image mixup (probability)
'mixup': (1, 0.0, 1.0), # image mixup (probability)
'copy_paste': (1, 0.0, 1.0)} # segment copy-paste (probability)

with open(opt.hyp, errors='ignore') as f:
hyp = yaml.safe_load(f) # load hyps dict
if 'anchors' not in hyp: # anchors commented in hyp.yaml
hyp['anchors'] = 3
if opt.noautoanchor:
del hyp['anchors'], meta['anchors']
opt.noval, opt.nosave, save_dir = True, True, Path(opt.save_dir) # only val/save final epoch
# ei = [isinstance(x, (int, float)) for x in hyp.values()] # evolvable indices
evolve_yaml, evolve_csv = save_dir / 'hyp_evolve.yaml', save_dir / 'evolve.csv'
if opt.bucket:
os.system(f'gsutil cp gs://{opt.bucket}/evolve.csv {evolve_csv}') # download evolve.csv if exists

for _ in range(opt.evolve): # generations to evolve
if evolve_csv.exists(): # if evolve.csv exists: select best hyps and mutate
# Select parent(s)
parent = 'single' # parent selection method: 'single' or 'weighted'
x = np.loadtxt(evolve_csv, ndmin=2, delimiter=',', skiprows=1)
n = min(5, len(x)) # number of previous results to consider
x = x[np.argsort(-fitness(x))][:n] # top n mutations
w = fitness(x) - fitness(x).min() + 1E-6 # weights (sum > 0)
if parent == 'single' or len(x) == 1:
# x = x[random.randint(0, n - 1)] # random selection
x = x[random.choices(range(n), weights=w)[0]] # weighted selection
elif parent == 'weighted':
x = (x * w.reshape(n, 1)).sum(0) / w.sum() # weighted combination

# Mutate
mp, s = 0.8, 0.2 # mutation probability, sigma
npr = np.random
npr.seed(int(time.time()))
g = np.array([meta[k][0] for k in hyp.keys()]) # gains 0-1
ng = len(meta)
v = np.ones(ng)
while all(v == 1): # mutate until a change occurs (prevent duplicates)
v = (g * (npr.random(ng) < mp) * npr.randn(ng) * npr.random() * s + 1).clip(0.3, 3.0)
for i, k in enumerate(hyp.keys()): # plt.hist(v.ravel(), 300)
hyp[k] = float(x[i + 7] * v[i]) # mutate

# Constrain to limits
for k, v in meta.items():
hyp[k] = max(hyp[k], v[1]) # lower limit
hyp[k] = min(hyp[k], v[2]) # upper limit
hyp[k] = round(hyp[k], 5) # significant digits

# Train mutation
results = train(hyp.copy(), opt, device, callbacks)
callbacks = Callbacks()
# Write mutation results
keys = ('metrics/precision', 'metrics/recall', 'metrics/mAP_0.5', 'metrics/mAP_0.5:0.95', 'val/box_loss',
'val/obj_loss', 'val/cls_loss')
print_mutation(keys, results, hyp.copy(), save_dir, opt.bucket)

# Plot results
plot_evolve(evolve_csv)
LOGGER.info(f'Hyperparameter evolution finished {opt.evolve} generations\n'
f"Results saved to {colorstr('bold', save_dir)}\n"
f'Usage example: $ python train.py --hyp {evolve_yaml}')


def run(**kwargs):
# Usage: import train; train.run(data='coco128.yaml', imgsz=320, weights='yolov5m.pt')
opt = parse_opt(True)
for k, v in kwargs.items():
setattr(opt, k, v)
main(opt)
return opt


if __name__ == "__main__":
opt = parse_opt()
main(opt)

圖片、影片與串流偵測

先使用一張已知內容的圖片確認權重能載入,再測試影片或相機。若相機沒有畫面,應先獨立檢查影像來源,不要把資料讀取問題直接當成模型辨識失敗。

除了可偵測圖片外,也能偵測影片、資料夾、webcam、即時串流、網頁上的影片

  • 範例(即時辨識):
    1
    python detect.py --weights best.pt --conf-thres 0.5 --img-size 640 --view-img --name detect-run --project runs/detect --save-crop --save-txt --vid-stride 20 --source 0
    --weights :則可用來指定預訓練的模型。ex:--weights best.pt
    --source:file.jpg#圖片、file.mp4#影片、dir/#資料夾、0#攝像頭(即時辨識)。
    --img-size :可以指定影像的大小,對於偵測比較小的物件時,可以加大影像的大小,預設的影像大小為 640。
    --iou-thres :是設定 IoU 門檻值。
    --conf-thres :則是設定信心度門檻值。
    --cuda device :指定運算裝置,例如 GPU 編號或 cpu。預設值請以所用腳本的 --help 為準;原文的 --cuda device 標示應對照實際 --device 參數。
    --save-txt:保存結果到*.txt。
    --save-conf:搭配 --save-txt 保存偵測框的信心值。
    --view-img:顯示視窗圖片。
    --nosave:不儲存輸出的圖片或影片。
    --classes:依類別編號過濾;實際參數拼法應為 --classes,並依腳本說明提供編號。
    --update:更新所有模型。
    --project:將驗證結果保存到自訂資料夾。ex:--project runs/detect
    --name:設定本次輸出資料夾名稱。ex:--name yolov5s-detect
    --exist-ok:允許使用既有輸出名稱,不自動遞增編號;執行前留意原有輸出。
    • (查看更多指令說明):

      在 Anaconda Prompt (yolov5) 上輸入:

      1
      python detect.py -h

detect.py

detect.py 中文修改補充(點擊展開)
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
43
44
45
46
47
48
49
50
51
52
53
54
55
56
57
58
59
60
61
62
63
64
65
66
67
68
69
70
71
72
73
74
75
76
77
78
79
80
81
82
83
84
85
86
87
88
89
90
91
92
93
94
95
96
97
98
99
100
101
102
103
104
105
106
107
108
109
110
111
112
113
114
115
116
117
118
119
120
121
122
123
124
125
126
127
128
129
130
131
132
133
134
135
136
137
138
139
140
141
142
143
144
145
146
147
148
149
150
151
152
153
154
155
156
157
158
159
160
161
162
163
164
165
166
167
168
169
170
171
172
173
174
175
176
177
178
179
180
181
182
183
184
185
186
187
188
189
190
191
192
193
194
195
196
197
198
199
200
201
202
203
204
205
206
207
208
209
210
211
212
213
214
215
216
217
218
219
220
221
222
223
224
225
226
227
228
229
230
231
232
233
234
235
236
237
238
239
240
241
242
243
244
245
246
247
248
249
250
251
252
253
254
255
256
257
258
259
260
261
262
263
264
265
266
267
268
269
270
271
272
273
274
275
276
277
278
279
280
281
# YOLOv5 🚀 by Ultralytics, GPL-3.0 license
"""
運行YOLOv5檢測推斷圖像,視頻,目錄,glob, YouTube,網絡攝像頭,etc等。

用法 - 來源:
$ python detect.py --weights yolov5s.pt --source 0 # webcam
img.jpg # image
vid.mp4 # video
screen # screenshot
path/ # directory
'path/*.jpg' # glob
'https://youtu.be/Zgi9g1ksQHc' # YouTube
'rtsp://example.com/media.mp4' # RTSP, RTMP, HTTP stream

用法 - 格式:
$ python detect.py --weights yolov5s.pt # PyTorch
yolov5s.torchscript # TorchScript
yolov5s.onnx # ONNX Runtime or OpenCV DNN with --dnn
yolov5s_openvino_model # OpenVINO
yolov5s.engine # TensorRT
yolov5s.mlmodel # CoreML (macOS-only)
yolov5s_saved_model # TensorFlow SavedModel
yolov5s.pb # TensorFlow GraphDef
yolov5s.tflite # TensorFlow Lite
yolov5s_edgetpu.tflite # TensorFlow Edge TPU
yolov5s_paddle_model # PaddlePaddle
"""

import argparse
import os
import platform
import sys
from pathlib import Path

import torch

FILE = Path(__file__).resolve()
ROOT = FILE.parents[0] # YOLOv5 root directory
if str(ROOT) not in sys.path:
sys.path.append(str(ROOT)) # 將 ROOT 添加到 PATH
ROOT = Path(os.path.relpath(ROOT, Path.cwd())) # relative

from models.common import DetectMultiBackend
from utils.dataloaders import IMG_FORMATS, VID_FORMATS, LoadImages, LoadScreenshots, LoadStreams
from utils.general import (LOGGER, Profile, check_file, check_img_size, check_imshow, check_requirements, colorstr, cv2,
increment_path, non_max_suppression, print_args, scale_boxes, strip_optimizer, xyxy2xywh)
from utils.plots import Annotator, colors, save_one_box
from utils.torch_utils import select_device, smart_inference_mode


@smart_inference_mode()
def run(
weights=ROOT / 'yolov5s.pt', # 模型路徑或 triton URL
source=ROOT / 'data/images', # 文件/目錄/URL/glob/screen/0(網絡攝像頭)
data=ROOT / 'data/coco128.yaml', # dataset.yaml路徑
imgsz=(640, 640), # 推理大小(高度, 寬度)
conf_thres=0.25, # confidence 閾值
iou_thres=0.45, # NMS IOU 閾值
max_det=1000, # 每張圖片的最大檢測數
device='', # cuda 設備,即 0 或 0,1,2,3 或 cpu
view_img=False, # 顯示結果
save_txt=False, # 將結果保存到 *.txt
save_conf=False, # 在 --save-txt 標籤中保存信心
save_crop=False, # 保存裁剪的預測框
nosave=False, # 不保存圖片/視頻
classes=None, # 按類別過濾:--class 0,或--class 0 2 3
agnostic_nms=False, # class-agnostic NMS
augment=False, # 增強推理
visualize=False, # 可視化特徵
update=False, # 更新所有模型
project=ROOT / 'runs/detect', # 將結果保存到項目/名稱
name='exp', # 將結果保存到項目/名稱
exist_ok=False, # 現有項目/名稱可以,不要增加
line_thickness=3, # 邊界框厚度(pixels像素)
hide_labels=False, # 隱藏標籤
hide_conf=False, # hide confidences
half=False, # 使用 FP16 半精度推理
dnn=False, # 使用 OpenCV DNN 進行 ONNX 推理
vid_stride=1, # 視頻幀率步幅
):
source = str(source)
save_img = not nosave and not source.endswith('.txt') # 保存推理圖像
is_file = Path(source).suffix[1:] in (IMG_FORMATS + VID_FORMATS)
is_url = source.lower().startswith(('rtsp://', 'rtmp://', 'http://', 'https://'))
webcam = source.isnumeric() or source.endswith('.txt') or (is_url and not is_file)
screenshot = source.lower().startswith('screen')
if is_url and is_file:
source = check_file(source) # download

# 目錄
save_dir = increment_path(Path(project) / name, exist_ok=exist_ok) # increment run
(save_dir / 'labels' if save_txt else save_dir).mkdir(parents=True, exist_ok=True) # make dir

# 加載模型
device = select_device(device)
model = DetectMultiBackend(weights, device=device, dnn=dnn, data=data, fp16=half)
stride, names, pt = model.stride, model.names, model.pt
imgsz = check_img_size(imgsz, s=stride) # 檢查圖像大小

# 數據加載器
bs = 1 # batch_size
if webcam:
view_img = check_imshow(warn=True)
dataset = LoadStreams(source, img_size=imgsz, stride=stride, auto=pt, vid_stride=vid_stride)
bs = len(dataset)
elif screenshot:
dataset = LoadScreenshots(source, img_size=imgsz, stride=stride, auto=pt)
else:
dataset = LoadImages(source, img_size=imgsz, stride=stride, auto=pt, vid_stride=vid_stride)
vid_path, vid_writer = [None] * bs, [None] * bs

# 運行推理
model.warmup(imgsz=(1 if pt or model.triton else bs, 3, *imgsz)) # warmup
seen, windows, dt = 0, [], (Profile(), Profile(), Profile())
for path, im, im0s, vid_cap, s in dataset:
with dt[0]:
im = torch.from_numpy(im).to(model.device)
im = im.half() if model.fp16 else im.float() # uint8 to fp16/32
im /= 255 # 0 - 255 to 0.0 - 1.0
if len(im.shape) == 3:
im = im[None] # expand for batch dim

# 推理
with dt[1]:
visualize = increment_path(save_dir / Path(path).stem, mkdir=True) if visualize else False
pred = model(im, augment=augment, visualize=visualize)

# NMS
with dt[2]:
pred = non_max_suppression(pred, conf_thres, iou_thres, classes, agnostic_nms, max_det=max_det)

# 第二階段分類器(可選)
# pred = utils.general.apply_classifier(pred, classifier_model, im, im0s)

# 過程預測
for i, det in enumerate(pred): # 每張圖片
seen += 1
if webcam: # batch_size >= 1
p, im0, frame = path[i], im0s[i].copy(), dataset.count
s += f'{i}: '
else:
p, im0, frame = path, im0s.copy(), getattr(dataset, 'frame', 0)

p = Path(p) # to Path
save_path = str(save_dir / p.name) # im.jpg
txt_path = str(save_dir / 'labels' / p.stem) + ('' if dataset.mode == 'image' else f'_{frame}') # im.txt
s += '%gx%g ' % im.shape[2:] # print string
gn = torch.tensor(im0.shape)[[1, 0, 1, 0]] # normalization gain whwh
imc = im0.copy() if save_crop else im0 # for save_crop
annotator = Annotator(im0, line_width=line_thickness, example=str(names))
if len(det):
# 將框從 img_size 重新縮放為 im0 大小
det[:, :4] = scale_boxes(im.shape[2:], det[:, :4], im0.shape).round()

# Print結果
for c in det[:, 5].unique():
n = (det[:, 5] == c).sum() # 每class檢測
s += f"{n} {names[int(c)]}{'s' * (n > 1)}, " # add to string

# Write結果
for *xyxy, conf, cls in reversed(det):

if save_txt: # Write to file
xywh = (xyxy2xywh(torch.tensor(xyxy).view(1, 4)) / gn).view(-1).tolist() # normalized xywh # 歸一化的xywh
line = (cls, *xywh, conf) if save_conf else (cls, *xywh) # label 格式
with open(f'{txt_path}.txt', 'a') as f:
f.write(('%g ' * len(line)).rstrip() % line + '\n')

if save_img or save_crop or view_img: # Add bbox to image
c = int(cls) # integer class
label = None if hide_labels else (names[c] if hide_conf else f'{names[c]} {conf:.2f}')
annotator.box_label(xyxy, label, color=colors(c, True))
if save_crop:
save_one_box(xyxy, imc, file=save_dir / 'crops' / names[c] / f'{p.stem}.jpg', BGR=True)

# 串流結果
im0 = annotator.result()
if view_img:
if platform.system() == 'Linux' and p not in windows:
windows.append(p)
cv2.namedWindow(str(p), cv2.WINDOW_NORMAL | cv2.WINDOW_KEEPRATIO) # 允許調整窗口大小 (Linux)
cv2.resizeWindow(str(p), im0.shape[1], im0.shape[0])
cv2.imshow(str(p), im0) #(視窗名稱,顯示圖片)
cv2.waitKey(1) # 1 毫秒.

# 保存結果(帶檢測的圖像)
if save_img:
if dataset.mode == 'image':
cv2.imwrite(save_path, im0)
else: # 'video' or 'stream'
if vid_path[i] != save_path: # new video
vid_path[i] = save_path
if isinstance(vid_writer[i], cv2.VideoWriter):
vid_writer[i].release() # release previous video writer
if vid_cap: # video
fps = vid_cap.get(cv2.CAP_PROP_FPS)
w = int(vid_cap.get(cv2.CAP_PROP_FRAME_WIDTH))
h = int(vid_cap.get(cv2.CAP_PROP_FRAME_HEIGHT))
else: # stream
fps, w, h = 30, im0.shape[1], im0.shape[0]
save_path = str(Path(save_path).with_suffix('.mp4')) # 在結果視頻上強制 *.mp4 後綴
vid_writer[i] = cv2.VideoWriter(save_path, cv2.VideoWriter_fourcc(*'mp4v'), fps, (w, h))
vid_writer[i].write(im0)

# 提升在訓練時的效率,生成的"images"和"labels"可以用來加強訓練。
# 條件是辨識新的圖片或影片,做為新的訓練樣本
if len(det):
ok_file="images" #【有】辨識到的圖,存放的資料夾名稱
img_path = str(save_dir / ok_file / p.stem) +("_"+str(seen)+".jpg") # im.txt
if not os.path.isdir(str(save_dir / ok_file)):
os.makedirs(str(save_dir / ok_file))
cv2.imwrite(img_path,im0s) #(寫入路徑,圖片) #im0s為辨識前原始圖 #im0為辨識過後有眶圖
box_file="images_box" #【有】辨識到的圖,存放的資料夾名稱
img_path = str(save_dir / box_file / p.stem) +("_"+str(seen)+".jpg") # im.txt
if not os.path.isdir(str(save_dir / box_file)):
os.makedirs(str(save_dir / box_file))
cv2.imwrite(img_path,im0) #(寫入路徑,圖片) #im0s為辨識前原始圖 #im0為辨識過後有眶圖
else:
# 可以手動將沒有辨識到的圖,另外進行labelimg處理。
no_file="no_images" #【沒有】辨識到的圖,存放的資料夾名稱
img_path = str(save_dir / no_file / p.stem) +("_"+str(seen)+".jpg") # im.txt
if not os.path.isdir(str(save_dir / no_file)):
os.makedirs(str(save_dir / no_file))
cv2.imwrite(img_path,im0s) #(寫入路徑,圖片) #im0s為辨識前原始圖 #im0為辨識過後有眶圖

# Print時間(僅推理)
LOGGER.info(f"{s}{'' if len(det) else '(No detections), '}{dt[1].dt * 1E3:.1f}ms")

# Print結果
t = tuple(x.t / seen * 1E3 for x in dt) # speeds per image # 每幅圖像的速度
LOGGER.info(f'Speed: %.1fms pre-process, %.1fms inference, %.1fms NMS per image at shape {(1, 3, *imgsz)}' % t)
if save_txt or save_img:
s = f"\n{len(list(save_dir.glob('labels/*.txt')))} labels saved to {save_dir / 'labels'}" if save_txt else ''
LOGGER.info(f"Results saved to {colorstr('bold', save_dir)}{s}")
if update:
strip_optimizer(weights[0]) # 更新模型(修復 SourceChangeWarning)


def parse_opt():
parser = argparse.ArgumentParser()
parser.add_argument('--weights', nargs='+', type=str, default=ROOT / 'yolov5s.pt', help='(可選)模型路徑或 triton URL')
parser.add_argument('--source', type=str, default=ROOT / 'data/images', help='文件/目錄/URL/glob/screen/0(網絡攝像頭)')
parser.add_argument('--data', type=str, default=ROOT / 'data/coco128.yaml', help='(可選)dataset.yaml 路徑')
parser.add_argument('--imgsz', '--img', '--img-size', nargs='+', type=int, default=[480,640], help='推理大小 h,w')
parser.add_argument('--conf-thres', type=float, default=0.25, help='confidence 閾值')
parser.add_argument('--iou-thres', type=float, default=0.45, help='NMS IoU 閾值')
parser.add_argument('--max-det', type=int, default=1000, help='每張圖片的最大檢測數')
parser.add_argument('--device', default='', help='cuda 設備,即 0 或 0,1,2,3 或 cpu')
parser.add_argument('--view-img', action='store_true', help='顯示辨識結果')
parser.add_argument('--save-txt', action='store_true', help='將結果保存到 *.txt')
parser.add_argument('--save-conf', action='store_true', help='在 --save-txt 標籤中保存信心')
parser.add_argument('--save-crop', action='store_true', help='保存裁剪的預測框')
parser.add_argument('--nosave', action='store_true', help='不保存圖片/視頻')
parser.add_argument('--classes', nargs='+', type=int, help='按類別過濾:--classes 0,或--classes 0 2 3')
parser.add_argument('--agnostic-nms', action='store_true', help='class-agnostic NMS')
parser.add_argument('--augment', action='store_true', help='增強推理')
parser.add_argument('--visualize', action='store_true', help='可視化特徵')
parser.add_argument('--update', action='store_true', help='更新所有模型')
parser.add_argument('--project', default=ROOT / 'runs/detect', help='將結果保存到項目/名稱')
parser.add_argument('--name', default='exp', help='將結果保存到項目/名稱')
parser.add_argument('--exist-ok', action='store_true', help='現有項目/名稱可以,不要增加')
parser.add_argument('--line-thickness', default=1, type=int, help='邊界框厚度(pixels像素)')
parser.add_argument('--hide-labels', default=False, action='store_true', help='隱藏標籤')
parser.add_argument('--hide-conf', default=False, action='store_true', help='隱藏confidences')
parser.add_argument('--half', action='store_true', help='使用FP16半精度推斷')
parser.add_argument('--dnn', action='store_true', help='使用OpenCV DNN進行ONNX推斷')
parser.add_argument('--vid-stride', type=int, default=1, help='視頻幀率步幅')
opt = parser.parse_args()
opt.imgsz *= 2 if len(opt.imgsz) == 1 else 1 # expand
print_args(vars(opt))
return opt


def main(opt):
check_requirements(exclude=('tensorboard', 'thop'))
run(**vars(opt))


if __name__ == "__main__":
opt = parse_opt()
main(opt)

常見錯誤與處理方式

  1. OMP: Error #15: Initializing libomp.dylib, but found libiomp5.dylib already initialize
    • 辦法1:
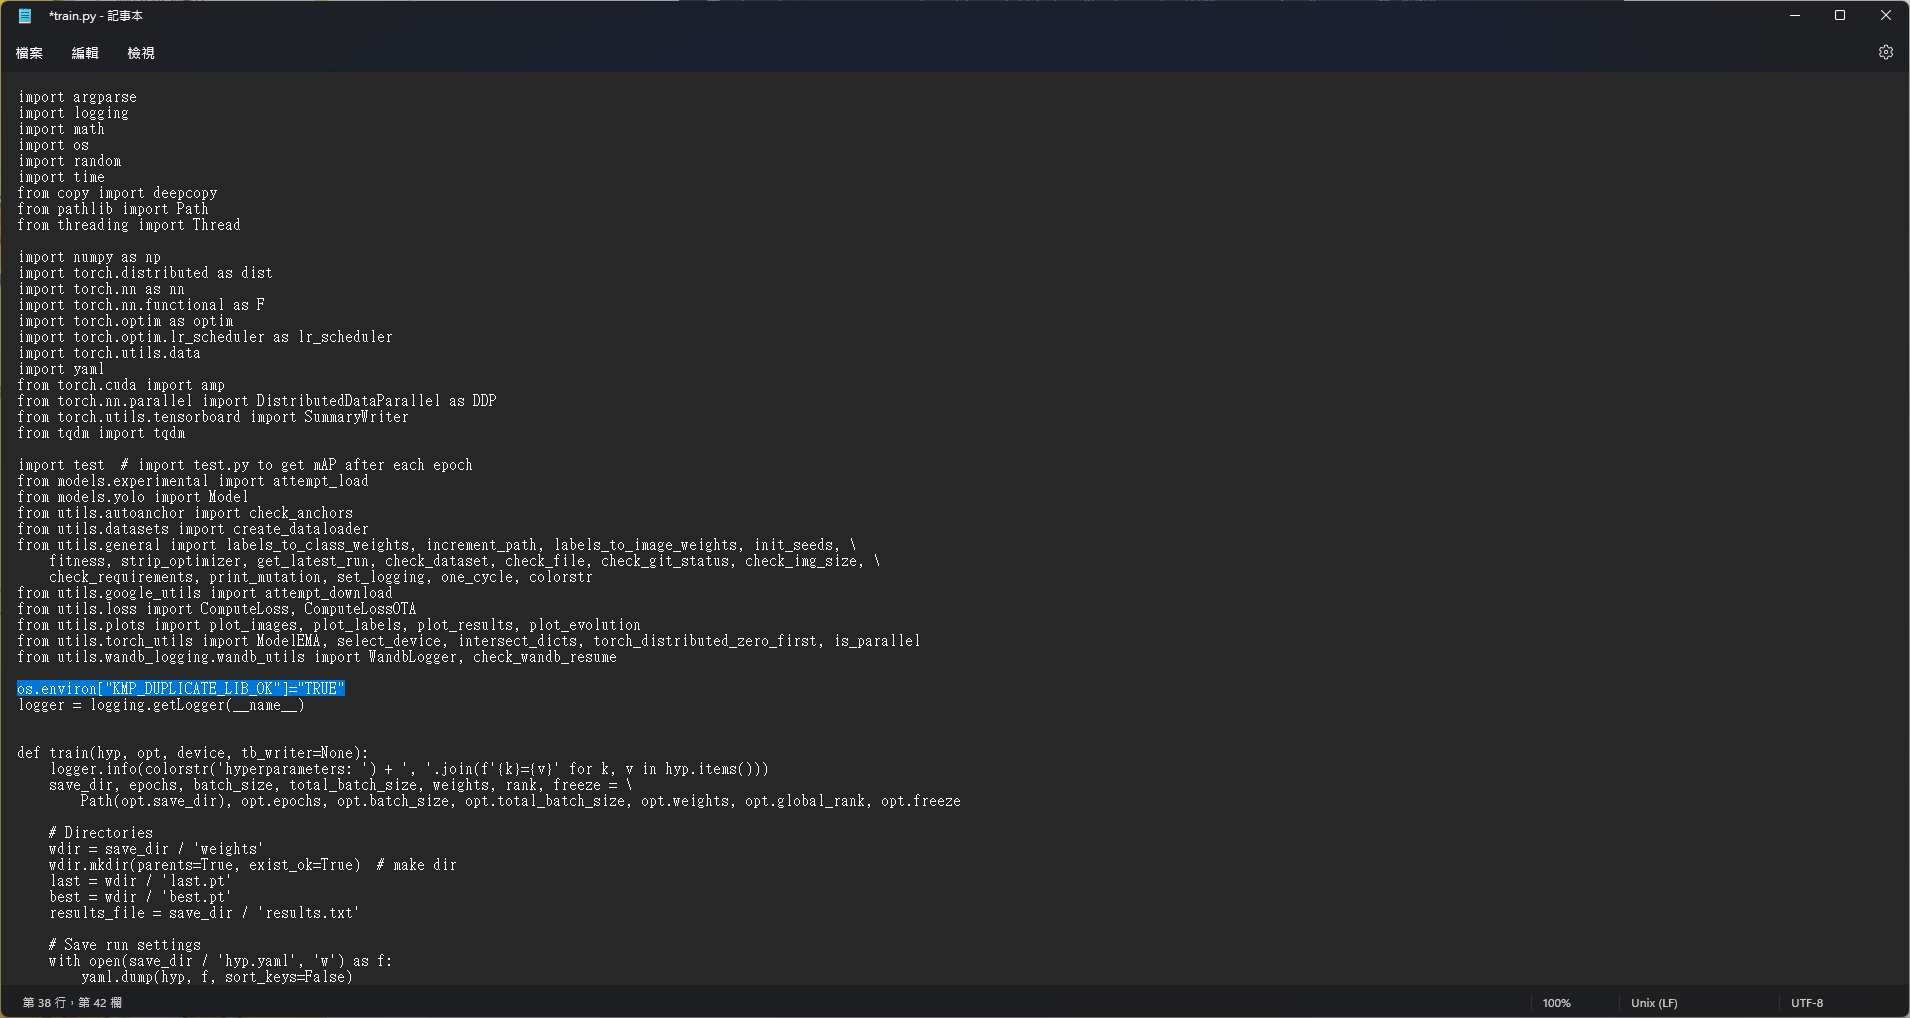
      原紀錄曾在 train.py 中使用下方 KMP_DUPLICATE_LIB_OK 繞行方式。它可能掩蓋 OpenMP 重複載入的衝突,應先檢查套件來源與相依版本,不把此設定視為已修復:
      1
      2
      import os
      os.environ["KMP_DUPLICATE_LIB_OK"]="TRUE"
      • 示意圖:
        常見錯誤與處理方式:原文圖片 17
    • 辦法2:
      舊筆記曾記錄刪除 \Anaconda3\pkgs 中含有 libomp.dylib 的快取。這不宜當作一般修復步驟;應先確認重複載入的執行期與套件來源,再在獨立環境中處理相依衝突。
      • PKGS的概念:
        在 Anaconda 環境中,可用 conda install,而python中是pip install,
        也可以使用 pip,但兩種工具混用時需核對套件來源與相依版本;不是所有套件都只能透過 conda install。
        在conda的設計中,目錄’pkgs’是下載、存放緩存,以及提取下載的conda包的地方。同時,anaconda一起攜帶的包也會放在這裡。
        建立 envs(環境)時,套件檔案可能以連結等方式重用 pkgs目錄,以減少重複檔案;實際方式依平台與設定而異。

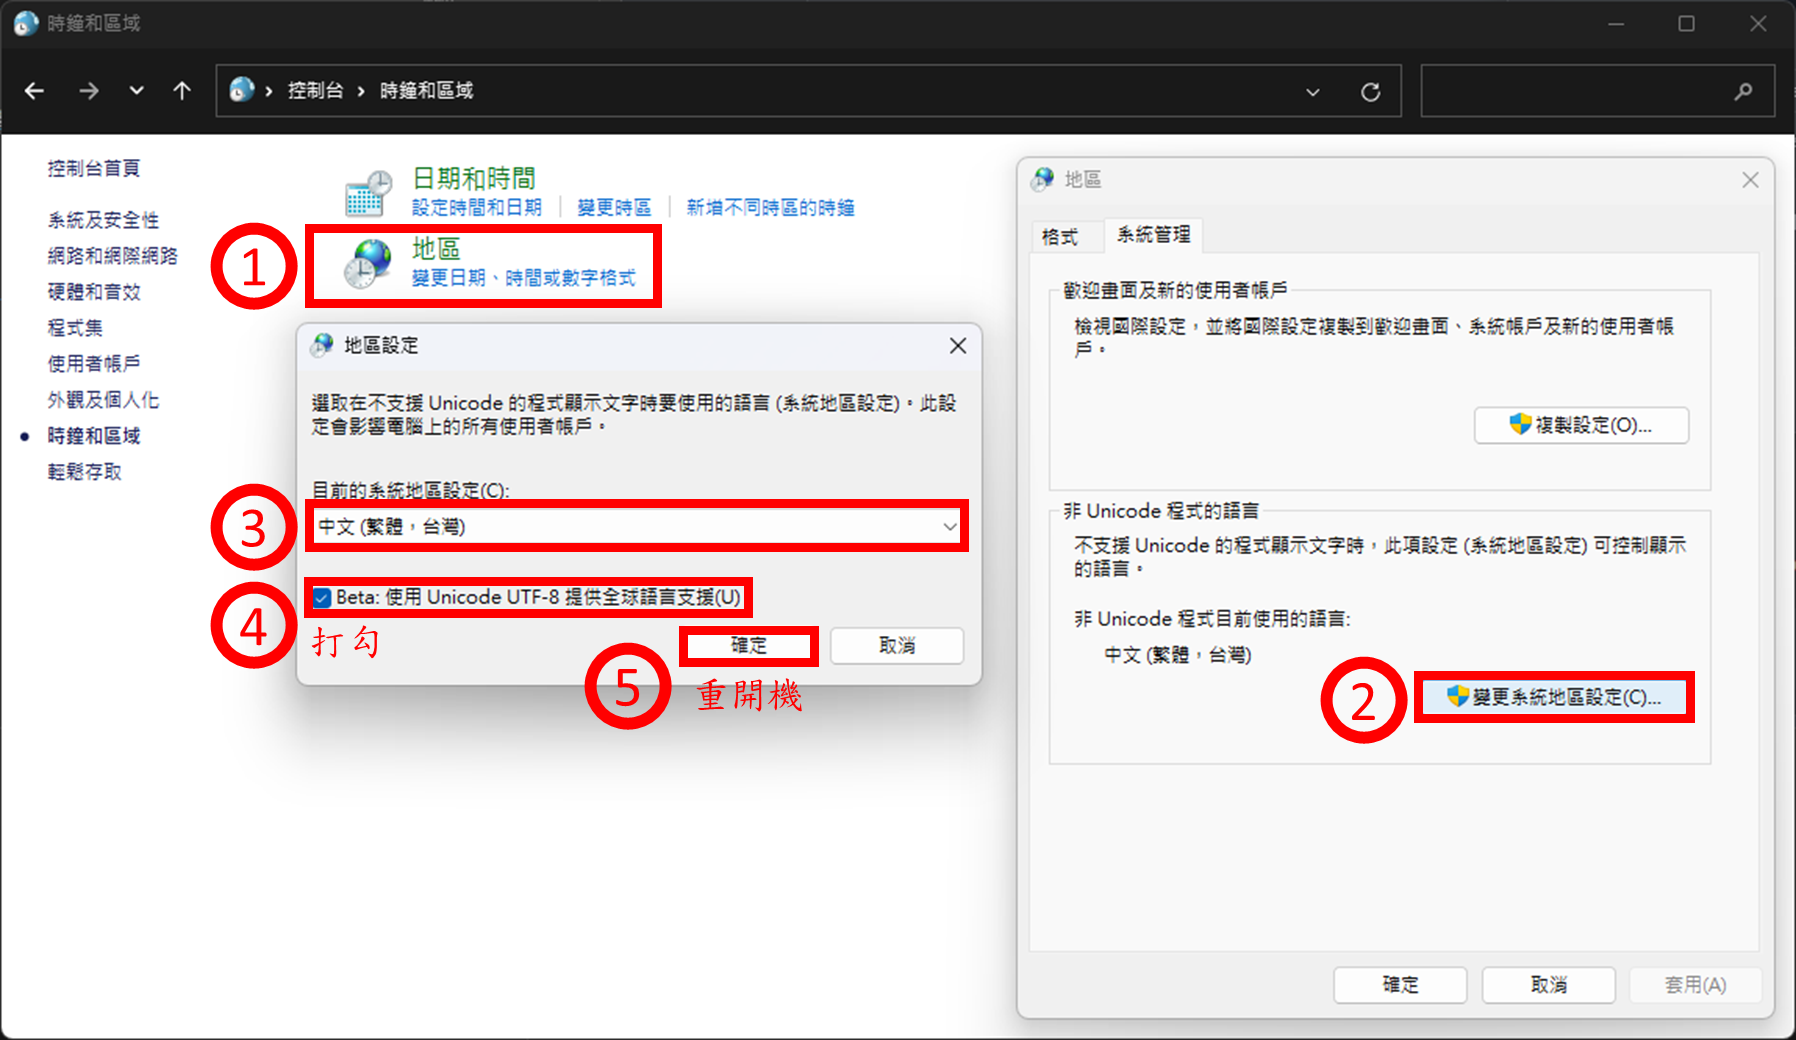
  1. UnicodeDecodeError: 'cp950' codec can't decode byte 0x93 in position 25: illegal multibyte sequence
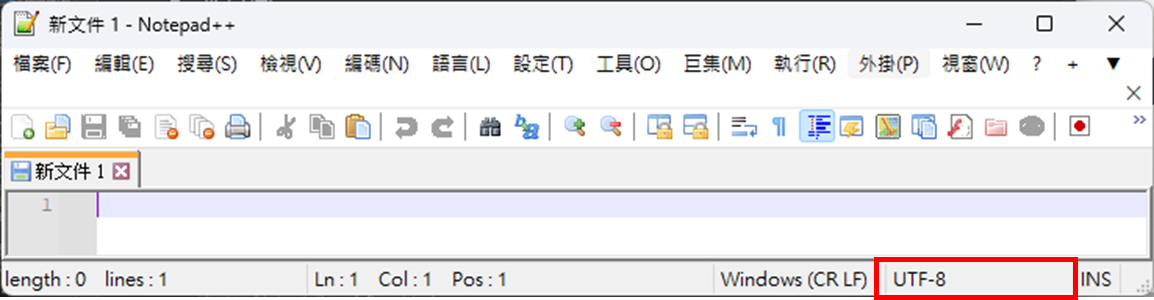
    這類錯誤表示讀取編碼與檔案內容不相符。先檢查 .yaml 的儲存編碼與程式讀取方式,不要直接把原因歸結為中文內容或作業系統。
  • 此專案使用 UTF-8 設定檔時,檔案的儲存與程式讀取編碼需一致。
    常見錯誤與處理方式:原文圖片 18
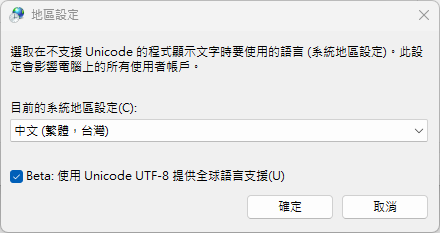
  • 可到控制台>時鐘和區域>地區>系統管理>變更系統地區設定> Bata:使用Unicode UTF-8提供全球語言支援
    的選項打勾前,先確認是否需要改變系統層級的編碼;本篇錯誤應優先檢查檔案及讀取端,不必先調整整個系統。
    常見錯誤與處理方式:原文圖片 19

  1. export GIT_PYTHON_REFRESH=quiet
    若 GitPython 找不到 Git,先確認 git 執行檔已安裝且可由 PATH 找到。quiet 只影響訊息處理,不會安裝 Git;下方保留當時的安裝指令。
    1
    conda install git

延伸實作紀錄

提升訓練效益

  • 如下方代碼所示:
    1
    2
    3
    4
    5
    6
    7
    8
    9
    10
    11
    12
    13
    14
    15
    16
    17
    18
    19
    20
    # 提升在訓練時的效率,生成的"images"和"labels"可以用來加強訓練。
    # 條件是辨識新的圖片或影片,做為新的訓練樣本
    if len(det):
    ok_file="images" #【有】辨識到的圖,存放的資料夾名稱
    img_path = str(save_dir / ok_file / p.stem) +("_"+str(seen)+".jpg") # im.txt
    if not os.path.isdir(str(save_dir / ok_file)):
    os.makedirs(str(save_dir / ok_file))
    cv2.imwrite(img_path,im0s) #(寫入路徑,圖片) #im0s為辨識前原始圖 #im0為辨識過後有眶圖
    box_file="images_box" #【有】辨識到的圖,存放的資料夾名稱
    img_path = str(save_dir / box_file / p.stem) +("_"+str(seen)+".jpg") # im.txt
    if not os.path.isdir(str(save_dir / box_file)):
    os.makedirs(str(save_dir / box_file))
    cv2.imwrite(img_path,im0) #(寫入路徑,圖片) #im0s為辨識前原始圖 #im0為辨識過後有眶圖
    else:
    # 可以手動將沒有辨識到的圖,另外進行labelimg處理。
    no_file="no_images" #【沒有】辨識到的圖,存放的資料夾名稱
    img_path = str(save_dir / no_file / p.stem) +("_"+str(seen)+".jpg") # im.txt
    if not os.path.isdir(str(save_dir / no_file)):
    os.makedirs(str(save_dir / no_file))
    cv2.imwrite(img_path,im0s) #(寫入路徑,圖片) #im0s為辨識前原始圖 #im0為辨識過後有眶圖

YOLO框取指定解析度的圖,可作為後續CNN訓練

將以下程式碼,放入到det[:, :4] = scale_boxes(im.shape[2:], det[:, :4], im0.shape).round()此行的上方,high和wight可依個人需求進行調整。

  • 如下方代碼所示:
    1
    2
    3
    4
    5
    6
    7
    8
    9
    10
    11
    12
    13
    14
    15
    16
    17
    18
    19
    if len(det):
    #####以下代碼#####
    #調整裁剪後的預測圖
    #裁減範圍若撞到圖片的邊緣,尺寸會有變化。
    high=50 #圖片裁減的調整值最低為12,若低於 12 裁減尺寸會有非預期結果
    wight=50 #圖片裁減的調整值最低為12,若低於 12 裁減尺寸會有非預期結果
    # 請勿變更
    ax=det[:, 0:1] ; ay=det[:, 1:2]
    bx=det[:, 2:3] ; by=det[:, 3:4]
    centerX=ax+((bx-ax)/2)
    centerY=ay+((by-ay)/2)
    #print(NewAX,NewAY,NewBX,NewBY)
    det[:, 0:1]=int((centerX)-((wight-11)/2))
    det[:, 1:2]=int((centerY)-((high-11)/2))
    det[:, 2:3]=int((centerX)+((wight-11)/2))
    det[:, 3:4]=int((centerY)+((high-11)/2))
    #####以上代碼#####
    # 將框從 img_size 重新縮放為 im0 大小
    det[:, :4] = scale_boxes(im.shape[2:], det[:, :4], im0.shape).round()

建立TCP/IP通訊

下方是我參考的 TCP/IP 範本。我曾依自己的需求調整,但本文只保留參考版本;閱讀時先分清伺服端與客戶端,再依自己的位址、連接埠及資料格式修改。

  1. 伺服端

    1
    2
    3
    4
    5
    6
    7
    8
    9
    10
    11
    12
    13
    14
    15
    16
    17
    18
    19
    20
    21
    22
    23
    24
    25
    26
    27
    28
    29
    30
    import socket

    # 設定IP和PORT
    HOST = '0.0.0.0'
    PORT = 7000
    # 建立伺服器
    s = socket.socket(socket.AF_INET, socket.SOCK_STREAM)
    s.bind((HOST, PORT))
    s.listen(5)
    # 輸出伺服器提示連線訊息
    print('server start at: %s:%s' % (HOST, PORT))
    print('wait for connection...')

    # 設定迴圈,不關閉伺服器
    while True:
    # 建立連線
    conn, addr = s.accept()
    print('connected by ' + str(addr)) # 輸出執行結果

    # 接收客戶端訊息
    indata = conn.recv(1024)
    print('recv: ' + indata.decode())

    # 傳送到客戶端訊息
    outdata = 'echo ' + indata.decode()
    conn.send(outdata.encode())
    conn.close()

    # 關閉伺服器
    s.close()
  2. 客戶端

    1
    2
    3
    4
    5
    6
    7
    8
    9
    10
    11
    12
    13
    14
    15
    16
    17
    18
    19
    import socket
    # 設定欲連線的伺服端的IP和PORT
    HOST = '0.0.0.0'
    PORT = 7000
    # 設定連線
    s = socket.socket(socket.AF_INET, socket.SOCK_STREAM)
    s.connect((HOST, PORT))

    # 傳送資料
    outdata = 'hello tcp'
    print('send: ' + outdata)
    s.send(outdata.encode())

    # 接收伺服端訊息
    indata = s.recv(1024) # 這個會delay,若必要時,可以設定超時跳出
    print('recv: ' + indata.decode())

    # 關閉客戶端連線
    s.close()

提升YOLO辨識度

以下整理改善資料集的方向,作為檢查清單。圖片數量與背景比例是參考建議,仍需依任務和驗證結果調整。

數據集方面

  1. 每個類別的圖像
    官方訓練建議提到每類約 1,500 張以上圖片,這是改善資料涵蓋度的方向,不是程式開始訓練的硬性限制。

  2. 每個類別的實例
    實例指的是標註的目標物件,不等於圖片張數;同一張圖片可包含多個實例。官方建議每類累積約 10,000 個實例,仍需配合場景與標註品質評估。

  3. 圖像的多樣性
    資料集應涵蓋預期使用的場景,例如光線、角度、距離與相機差異。依任務選擇變化,不必為了湊數加入無關圖片。

  4. 標註的一致性
    對任務指定的類別一致標註,避免同一類目標有時標、有時漏標,讓模型學到矛盾的訊號。

  5. 標註的精度
    依一致的規則讓框貼合目標,並抽查漏標、錯類與過大的框。標註品質需與資料量一起評估。
    背景圖像:背景圖像是圖像裡沒有感興趣目標的圖像,加到數據集以減少誤報(FP)。
    建議約0-10%的背景圖像,以幫助減少FP(COCO數據集有1000張背景圖像供參考,佔總數的1%)。

完成訓練後,先檢查什麼?

確認權重檔案確實存在,偵測指令讀取的是預期的檔案,並對照驗證圖片上的框、類別與漏判情況。訓練結束只表示流程完成,還需要用與訓練資料分開的圖片判斷是否符合使用需求。

資料切分與數量建議可查閱 Ultralytics 訓練資料說明;完整操作流程見自訂資料訓練教學。